Karpathy's ASD-STE100 tip, measured
Karpathy's tip: "Ask your LLM to explain something in ASD-STE100", a controlled language from aerospace maintenance manuals with "heavy constraints on clean writing style that I often find a lot more readable." I gave six models his tip as a one-line instruction and measured what it changed on the explain task the Skills page uses.
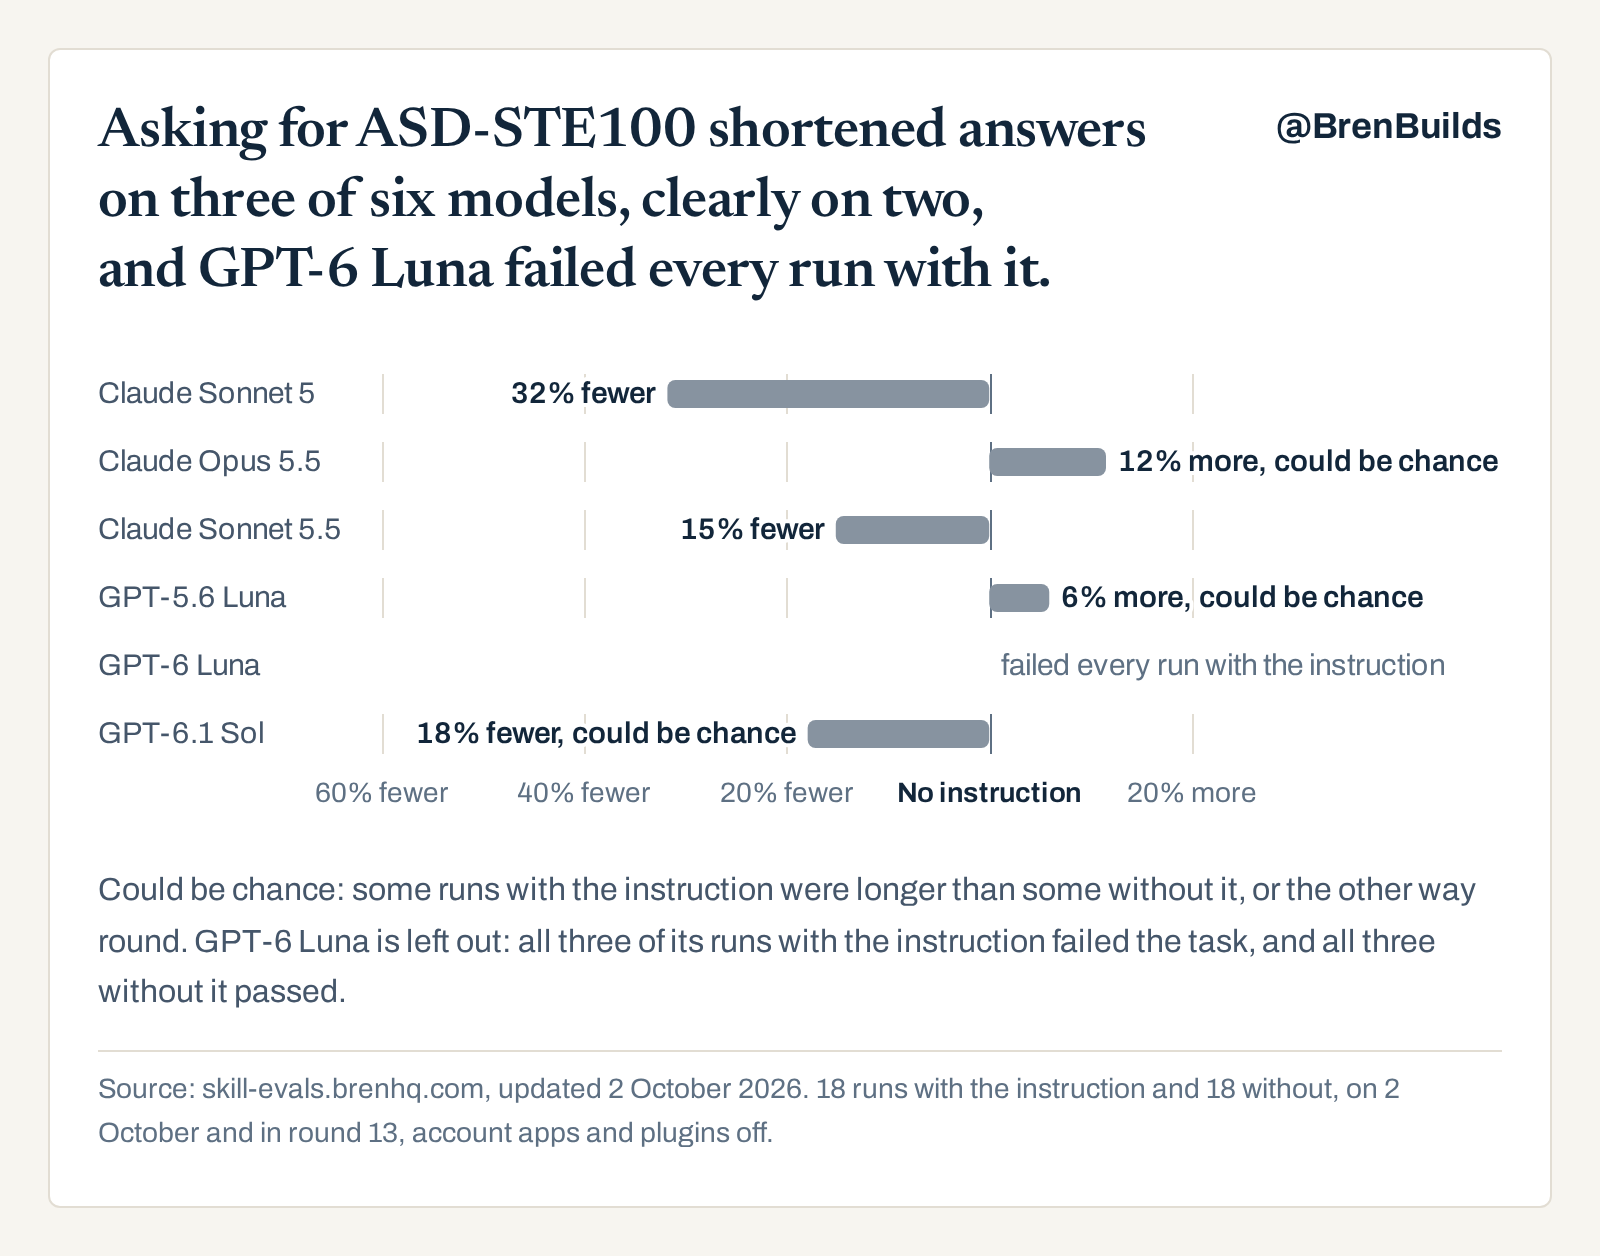
Asking for ASD-STE100 shortened answers on three of six models, clearly on two, and GPT-6 Luna failed every run with it.
Change in visible output tokens against no instruction, median of 3 runs a side, on the explain task: each model reads one 53-line Python file and explains it.
Could be chance: some runs with the instruction were longer than some without it, or the other way round. GPT-6 Luna is left out: all three of its runs with the instruction failed the task, and all three without it passed.
The table scrolls sideways on a small screen.
| Model | Output, no instruction | Output, ASD-STE100 | Change | Short sentences, no instruction | Short sentences, ASD-STE100 | Passed |
|---|---|---|---|---|---|---|
| Claude Sonnet 5Claude Code 2.1.284, default effort | 956 | 652 | 32% fewer | 53% | 100% | 6 of 6 |
| Claude Opus 5.5Claude Code 2.1.284, default effort | 988 | 1,102 | 12% more | 95% | 100% | 6 of 6 |
| Claude Sonnet 5.5Claude Code 2.1.284, default effort | 864 | 733 | 15% fewer | 100% | 100% | 6 of 6 |
| GPT-5.6 LunaCodex CLI 0.159.0, low effort | 236 | 250 | 6% more | 100% | 100% | 6 of 6 |
| GPT-6 LunaCodex CLI 0.159.0, low effort | 186 | 52 | not compared | 100% | 100% | 3 of 6 |
| GPT-6.1 SolCodex CLI 0.159.0, medium effort | 301 | 247 | 18% fewer | 100% | 100% | 6 of 6 |
Output counts visible output tokens, what the model writes minus its hidden thinking. Short sentences is the median share of an answer's sentences with 25 words or fewer, STE's limit for descriptive writing, counted roughly: code blocks left out, a sentence ending at a full stop or a line break. Passed counts runs with and without the instruction whose answer named ValueError and month.
Source: skill-evals.brenhq.com, updated 2 October 2026. 18 runs with the instruction and 18 without, on 2 October and in round 13, account apps and plugins off.
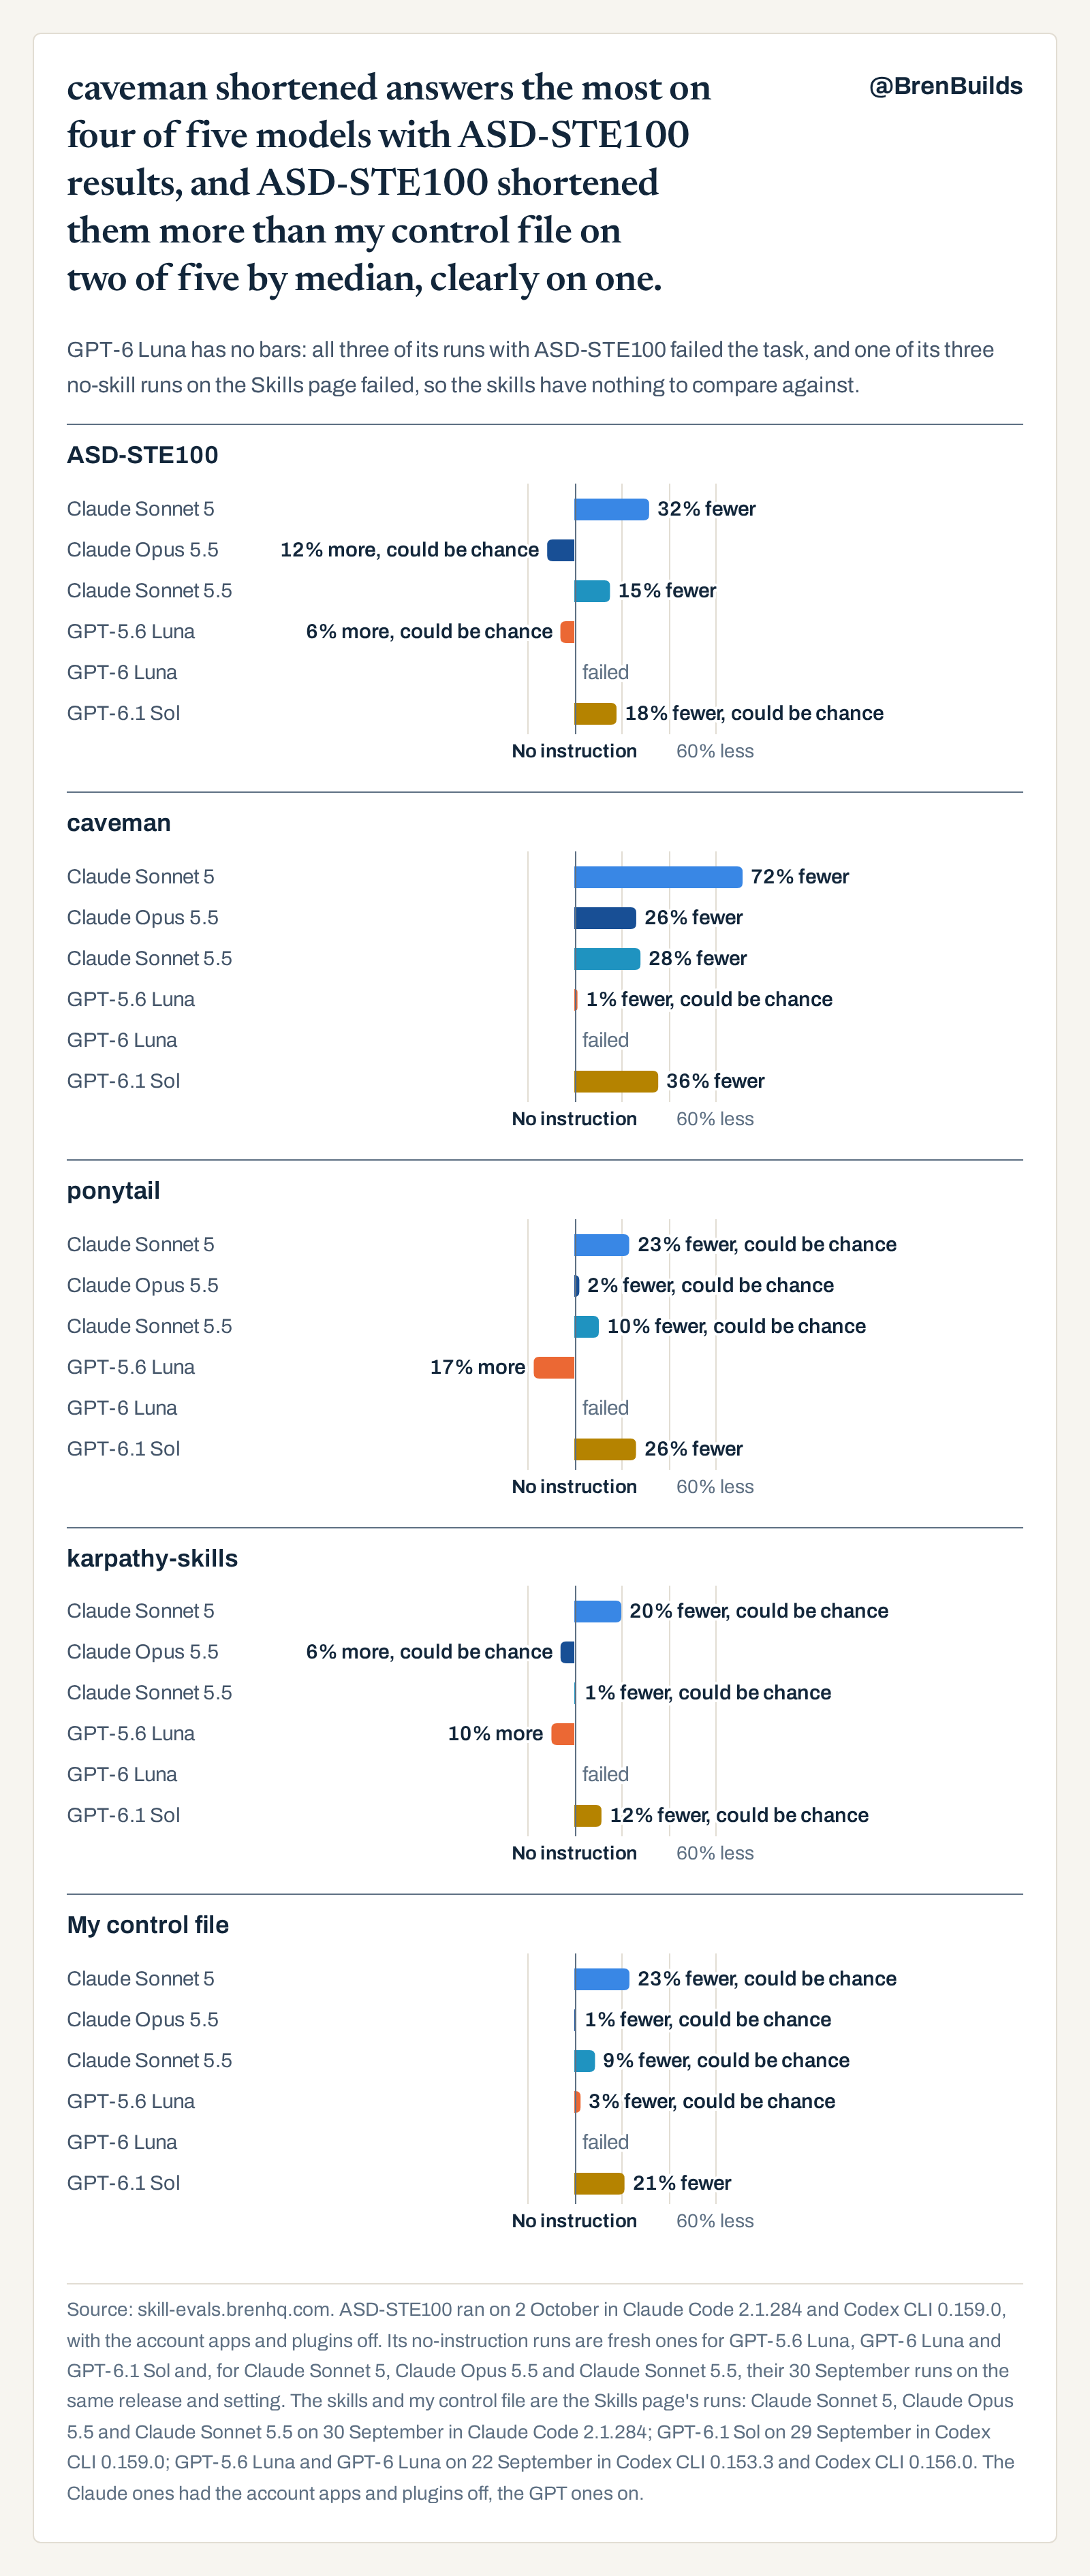
caveman shortened answers the most on four of five models with ASD-STE100 results, and ASD-STE100 shortened them more than my control file on two of five by median, clearly on one.
Change in visible output tokens against no instruction on the explain task, median of 3 runs a side. Each setup is against no-instruction runs on its own CLI release and setting, so these are separate experiments side by side, not one race under one setting. My control file is 365 words of generic project guidelines I wrote: not a token-saving skill, and not a neutral placebo either, since it asks for a review pass and edge-case handling.
GPT-6 Luna has no bars: all three of its runs with ASD-STE100 failed the task, and one of its three no-skill runs on the Skills page failed, so the skills have nothing to compare against.
ASD-STE100
caveman
ponytail
karpathy-skills
My control file
Source: skill-evals.brenhq.com. ASD-STE100 ran on 2 October in Claude Code 2.1.284 and Codex CLI 0.159.0, with the account apps and plugins off. Its no-instruction runs are fresh ones for GPT-5.6 Luna, GPT-6 Luna and GPT-6.1 Sol and, for Claude Sonnet 5, Claude Opus 5.5 and Claude Sonnet 5.5, their 30 September runs on the same release and setting. The skills and my control file are the Skills page's runs: Claude Sonnet 5, Claude Opus 5.5 and Claude Sonnet 5.5 on 30 September in Claude Code 2.1.284; GPT-6.1 Sol on 29 September in Codex CLI 0.159.0; GPT-5.6 Luna and GPT-6 Luna on 22 September in Codex CLI 0.153.3 and Codex CLI 0.156.0. The Claude ones had the account apps and plugins off, the GPT ones on.
How I ran it#
The instruction is one line, installed as CLAUDE.md for Claude Code and AGENTS.md for Codex CLI, the same way the Skills page installs every skill: "When you explain something, write the explanation in ASD-STE100, the Simplified Technical English controlled language specification." Each run starts the CLI on a fresh copy of a small Python project in the bench's Docker container and asks the model to explain how its 53-line file adds up monthly totals and what happens with a bad date. The account's apps and plugins are off.
The Claude models' runs without the instruction are their round 13 explain runs, on the same Claude Code release and setting. The GPT models got new runs without the instruction beside their STE runs, because their earlier ones had the apps and plugins on. Both Lunas ran at low effort and GPT-6.1 Sol at medium, as on the Skills page.
Karpathy's claim is readability, which this does not measure. The page measures length and one STE rule a script can count. The STE dictionary of approved words is ASD copyright and is not checked. A run with the instruction cost $0.00126 to $0.0897 at API prices. The run records are in results.json, under ste_runs and round13_runs.