Claude Haiku 5.5 vs GPT-6 Luna
Anthropic released Claude Haiku 5.5 on 7 October at GPT-6 Luna's price per token for prompts up to 100k tokens. I ran both through the same tests that day, at medium and at xhigh effort.
Speed#
At medium, Haiku 5.5 finished sooner than GPT-6 Luna by median, 7.3 against 7.6 s; at xhigh, GPT-6 Luna finished sooner than Haiku 5.5 by median, 9.0 against 15.2 s.
Hover or tap a row for every number; every run is in the table.
Medians of passed runs. One run failed (GPT-6 Luna, medium): it answered without reading the file, so its time is listed but not counted. A seventh run replaced it; it ran while other tests were running, unlike the rest. TPS is the rate the answer's visible text reached my terminal through each tool: its output tokens minus its hidden thinking, over the seconds from its first word to its last, counted only for runs whose text arrived in at least 20 separate bursts (six of six for Haiku 5.5, medium, three of six for GPT-6 Luna, medium, six of six for Haiku 5.5, xhigh and two of six for GPT-6 Luna, xhigh). It is not the provider's API speed, and Anthropic and OpenAI count tokens differently, so each TPS is in its own vendor's tokens. A median needs at least three runs that streamed, so GPT-6 Luna, xhigh shows none; its runs are in the table.
Where the seconds went, by median: Haiku 5.5, medium waited 3.8 s on the model outside its answer's text (500 thinking tokens in the answer reply) and streamed text for 2.5 s; GPT-6 Luna, medium waited 2.5 s on the model outside its answer's text (0 thinking tokens in the answer reply) and streamed text for 1.6 s; Haiku 5.5, xhigh waited 12.0 s on the model outside its answer's text (2,087 thinking tokens in the answer reply) and streamed text for 2.4 s; GPT-6 Luna, xhigh waited 3.5 s on the model outside its answer's text (136 thinking tokens in the answer reply) and streamed text for 1.0 s. The rest is each tool starting up, running its file read and exiting.
The table scrolls sideways on a small screen.
| Model and effort | Run | Seconds | Visible tokens | Thinking tokens | Bursts | TPS |
|---|---|---|---|---|---|---|
| Haiku 5.5, medium | 1 | 6.7 | 542 | 348 | 113 | 229.6 |
| Haiku 5.5, medium | 2 | 6.4 | 480 | 336 | 104 | 218.9 |
| Haiku 5.5, medium | 3 | 7.3 | 447 | 550 | 105 | 212.5 |
| Haiku 5.5, medium | 4 | 7.9 | 620 | 530 | 139 | 213.5 |
| Haiku 5.5, medium | 5 | 7.4 | 546 | 493 | 123 | 210.4 |
| Haiku 5.5, medium | 6 | 7.4 | 610 | 506 | 132 | 219.3 |
| GPT-6 Luna, medium | 1 | 7.4 | 111 | 0 | 11 | too few bursts |
| GPT-6 Luna, medium | 2 | 8.0 | 106 | 0 | 81 | 57.8 |
| GPT-6 Luna, medium | 3 | 3.8, failed | 31 | 0 | 17 | |
| GPT-6 Luna, medium | 4 | 5.1 | 111 | 0 | 9 | too few bursts |
| GPT-6 Luna, medium | 5 | 8.1 | 115 | 0 | 90 | 58.5 |
| GPT-6 Luna, medium | 6 | 7.7 | 111 | 0 | 86 | 58.6 |
| GPT-6 Luna, medium | 7 | 6.8 | 91 | 0 | 7 | too few bursts |
| Haiku 5.5, xhigh | 1 | 10.6 | 541 | 1240 | 109 | 228.2 |
| Haiku 5.5, xhigh | 2 | 16.1 | 643 | 2088 | 117 | 269.8 |
| Haiku 5.5, xhigh | 3 | 8.9 | 702 | 761 | 153 | 228.5 |
| Haiku 5.5, xhigh | 4 | 15.3 | 589 | 2086 | 118 | 243.5 |
| Haiku 5.5, xhigh | 5 | 16.1 | 593 | 2500 | 107 | 277.9 |
| Haiku 5.5, xhigh | 6 | 15.1 | 652 | 2266 | 109 | 280.7 |
| GPT-6 Luna, xhigh | 1 | 8.5 | 90 | 125 | 9 | too few bursts |
| GPT-6 Luna, xhigh | 2 | 10.5 | 99 | 155 | 71 | 61.5 |
| GPT-6 Luna, xhigh | 3 | 9.4 | 103 | 140 | 6 | too few bursts |
| GPT-6 Luna, xhigh | 4 | 6.6 | 90 | 120 | 8 | too few bursts |
| GPT-6 Luna, xhigh | 5 | 9.9 | 86 | 132 | 61 | 61.1 |
| GPT-6 Luna, xhigh | 6 | 7.9 | 103 | 160 | 8 | too few bursts |
Source: skill-evals.brenhq.com, updated 7 October 2026. 25 runs on 7 October, one at a time, six per model and effort, seven for GPT-6 Luna, medium: Claude Haiku 5.5 in Claude Code 2.1.284, GPT-6 Luna in Codex CLI 0.159.0, apps and plugins off.
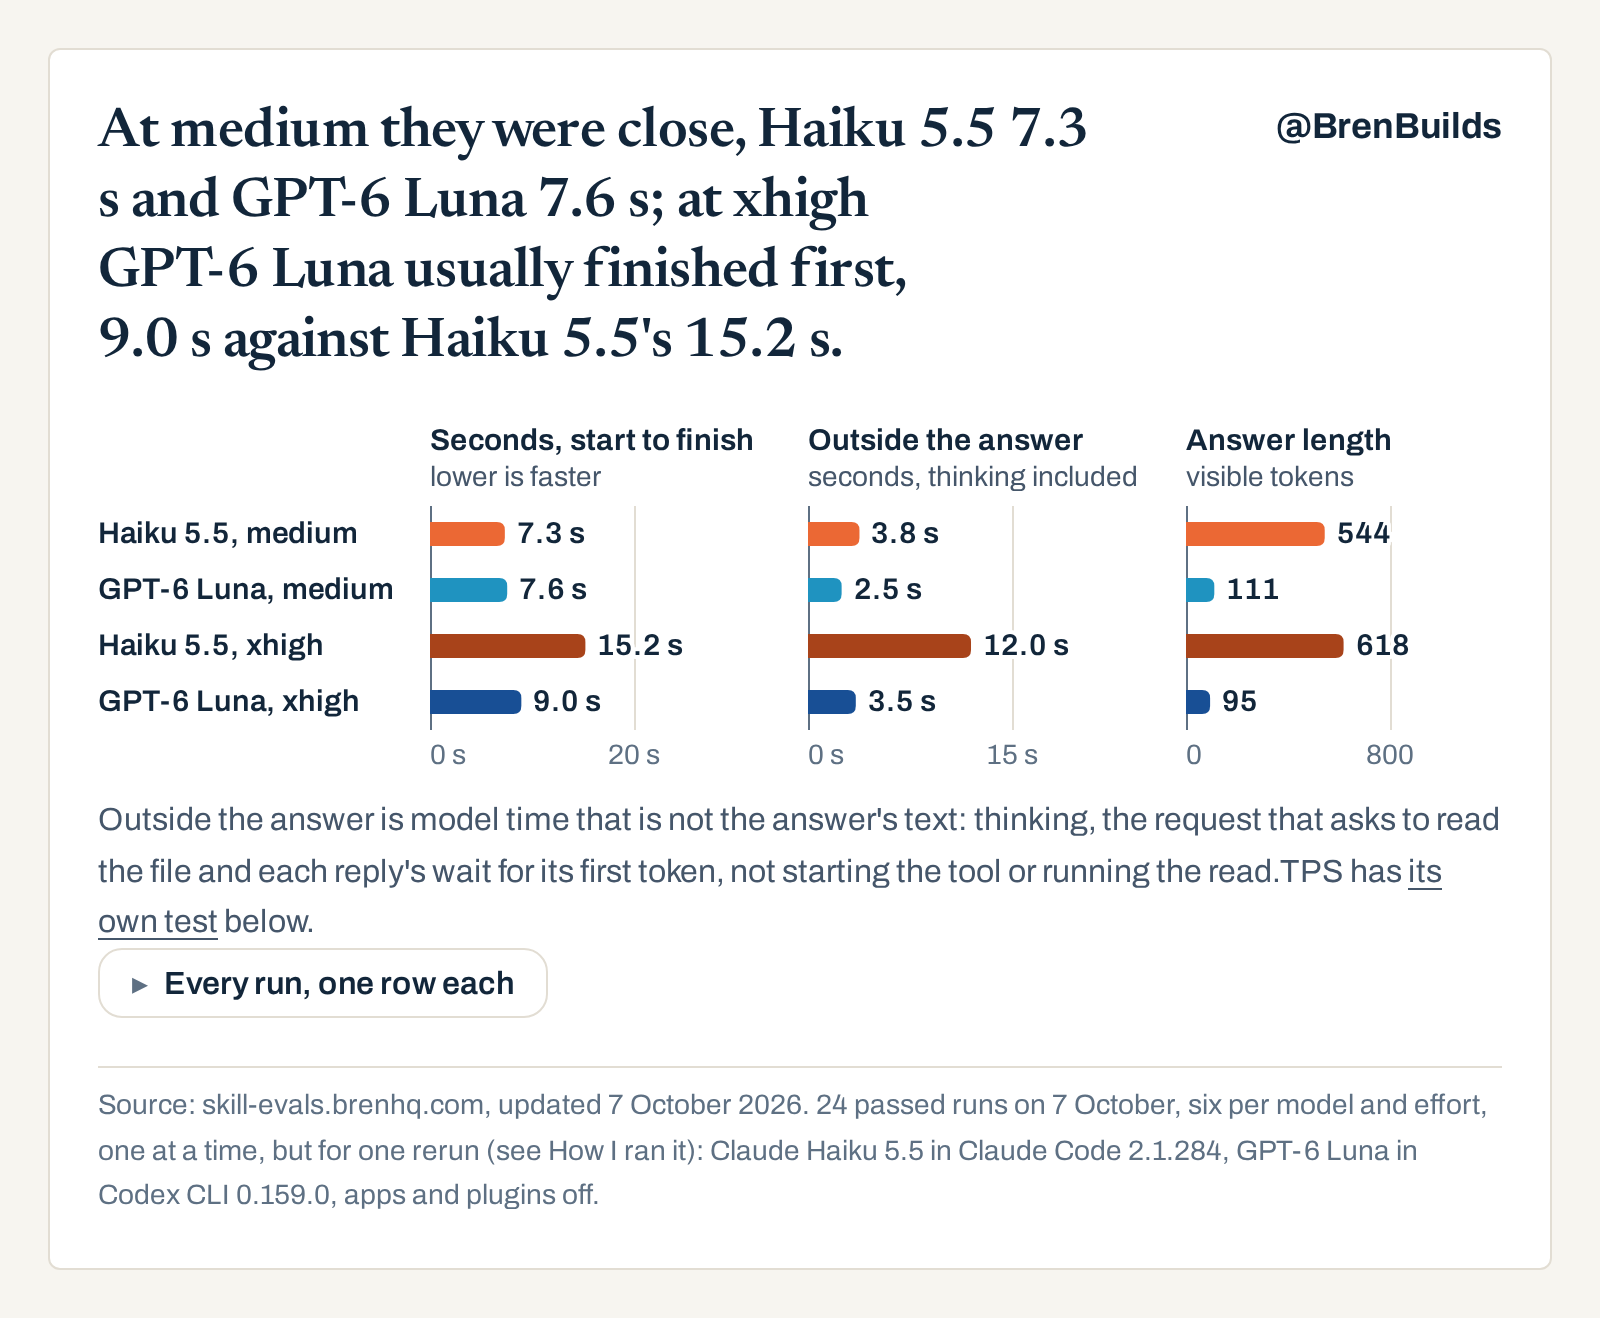
The race#
- Haiku 5.5, medium: 6.4 to 7.9 s
- GPT-6 Luna, medium: 5.1 to 8.1 s, and 1 failed run
- Haiku 5.5, xhigh: 8.9 to 16.1 s
- GPT-6 Luna, xhigh: 6.6 to 10.5 s
Skills#
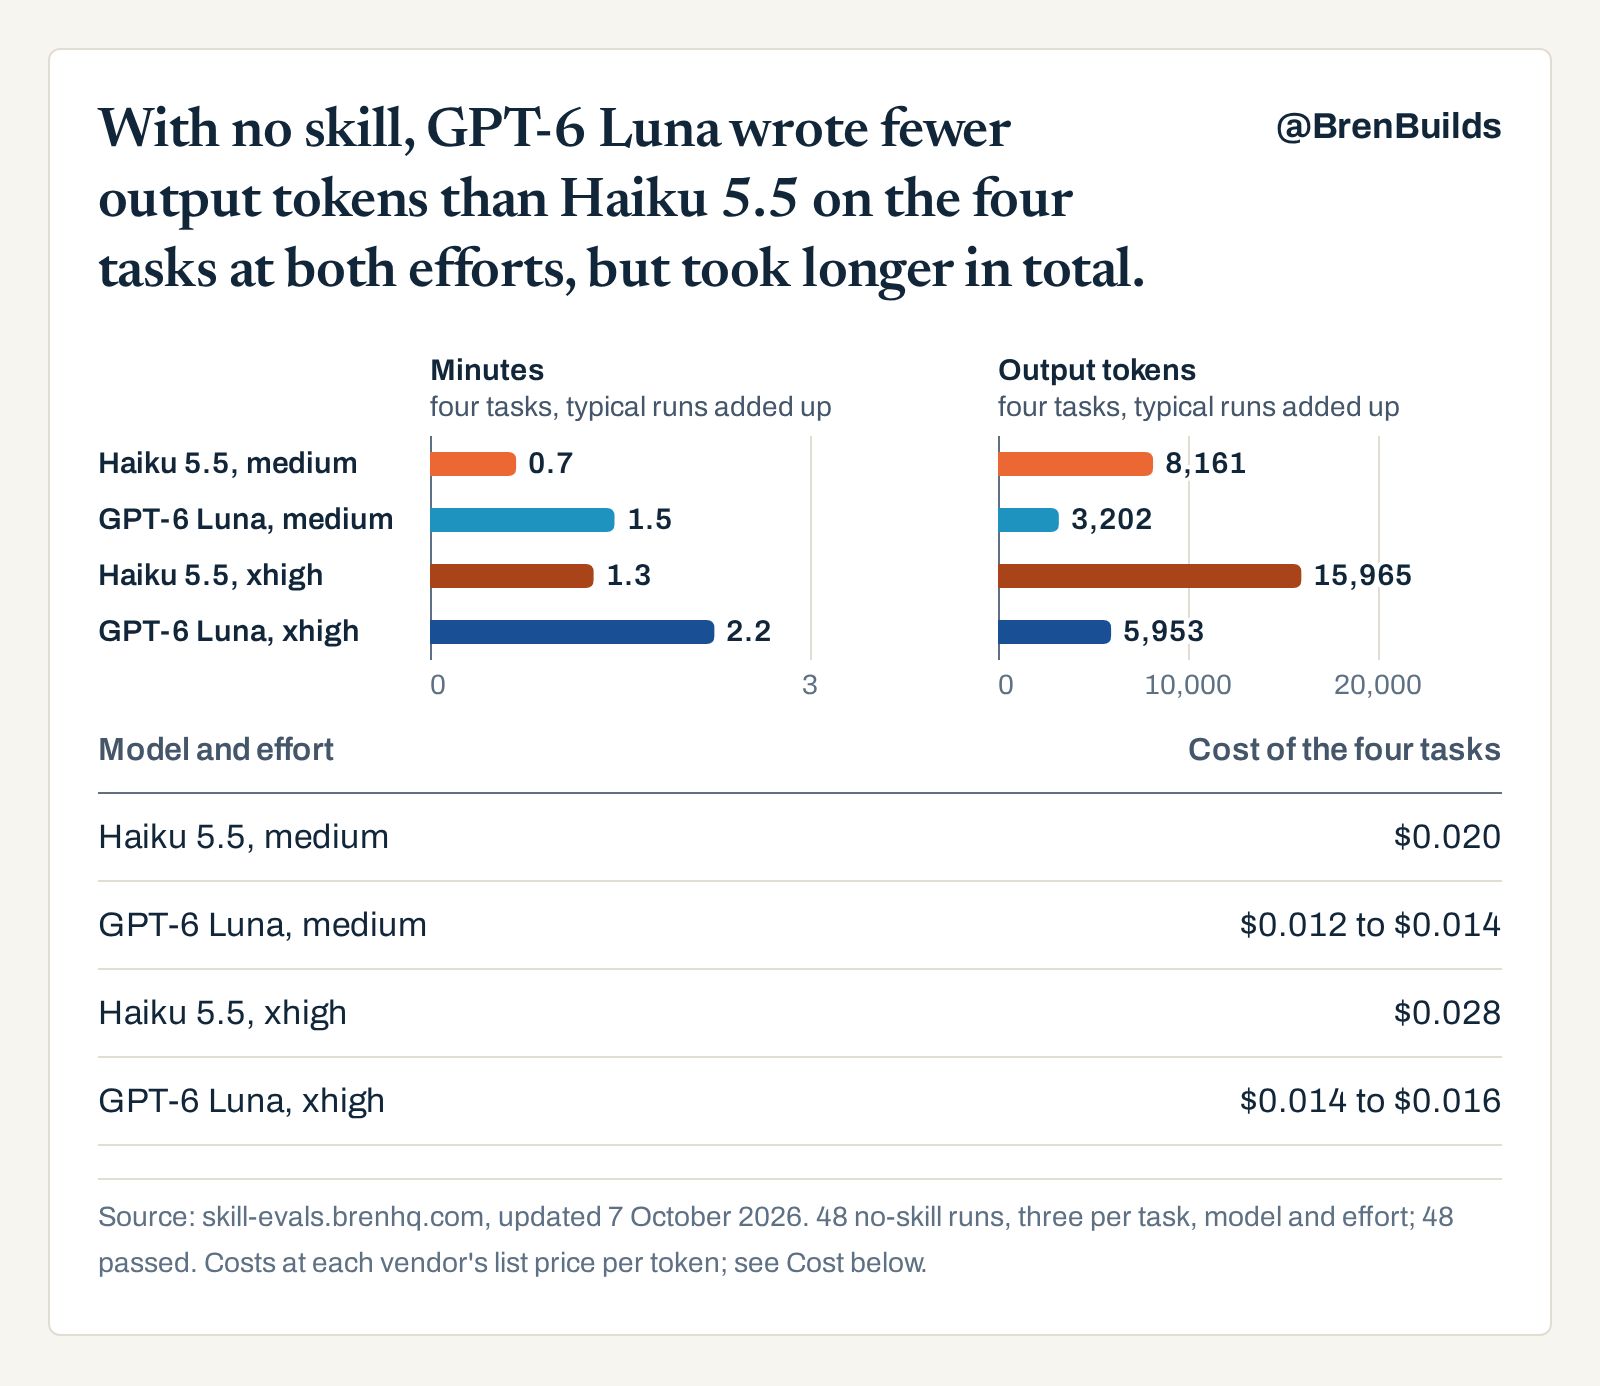
With no skill, by median across the four tasks: at medium, GPT-6 Luna cost less, $0.012 to $0.014 against Haiku 5.5's $0.020; at xhigh, GPT-6 Luna cost less, $0.014 to $0.016 against Haiku 5.5's $0.028.
With no skill. Hover or tap a row for each task.
| Model and effort | Cost of the four tasks, sum of task medians | Passed |
|---|---|---|
| Haiku 5.5, medium | $0.020 | 12 of 12 |
| GPT-6 Luna, medium | $0.012 to $0.014 | 12 of 12 |
| Haiku 5.5, xhigh | $0.028 | 12 of 12 |
| GPT-6 Luna, xhigh | $0.014 to $0.016 | 12 of 12 |
Held-out tests, new inputs for the same behavior, passed on the no-skill coding runs: Haiku 5.5, medium 9 of 9, GPT-6 Luna, medium 9 of 9, Haiku 5.5, xhigh 9 of 9, GPT-6 Luna, xhigh 9 of 9.
The explain, feature, bug fix and build tasks, three runs each with no skill; each bar adds up the four tasks' medians. Costs use each vendor's list prices (see Cost below): Claude Code 2.1.284 estimates Haiku 5.5's runs at Opus 5.5's prices because it predates Haiku 5.5, and GPT-6 Luna's are a range because Codex logs no cache writes.
Source: skill-evals.brenhq.com, updated 7 October 2026. 48 no-skill runs, three per task, model and effort; 48 passed. Costs at each vendor's list price per token; see Cost below.
Token-saving skills hit their claimed number in 0 of 20 checks on Haiku 5.5 and GPT-6 Luna.
Each skill against no skill on the same task, model and effort, by median of three runs. Could be chance: the two sides' runs overlap.
The table scrolls sideways on a small screen.
| Claim | Claimed | Haiku 5.5, medium | GPT-6 Luna, medium | Haiku 5.5, xhigh | GPT-6 Luna, xhigh |
|---|---|---|---|---|---|
| caveman, shorter answers | 65% | 13% fewer, could be chance | 34% fewer | 3% fewer, could be chance | 30% fewer |
| ponytail, less code | 54% | 14% less | 8% less, could be chance | 12% less | 30% less |
| ponytail, fewer tokens | 22% | 12% fewer, could be chance | 5% more, could be chance | 24% more, could be chance | 45% more |
| ponytail, cheaper | 20% | 4% pricier, could be chance | 37% pricier | 25% pricier | 50% pricier |
| ponytail, faster | 27% | 4% slower, could be chance | 24% slower, could be chance | 33% slower | 20% faster, could be chance |
| karpathy-skills, less code | no number | 4% less, could be chance | 10% less, could be chance | 4% less, could be chance | 21% less |
Source: skill-evals.brenhq.com, updated 7 October 2026. Explain task for caveman, build task for ponytail and karpathy-skills. Claims from each skill's own README or description, as on the Skills page. 4 of 240 skills runs failed their task's check: two on GPT-6 Luna, medium, explain task with placebo; two on GPT-6 Luna, medium, explain task with ponytail. GPT-6 Luna's cost change uses the low end of its cost range on both sides.

ASD-STE100#
By median, asking for ASD-STE100 shortened answers on one of the four model and effort pairs, clearly on none. Every run with it passed.
The explain task's answer, visible output tokens, by median of three runs with the one-line instruction and three without.
| Model and effort | No instruction | ASD-STE100 | Change | Passed with it |
|---|---|---|---|---|
| Haiku 5.5, medium | 601 | 785 | 31% more | 3 of 3 |
| GPT-6 Luna, medium | 176 | 167 | 5% fewer, could be chance | 3 of 3 |
| Haiku 5.5, xhigh | 701 | 1089 | 55% more | 3 of 3 |
| GPT-6 Luna, xhigh | 176 | 191 | 9% more, could be chance | 3 of 3 |
On the ASD-STE100 page, GPT-6 Luna failed every run with the instruction at low effort; here it ran at medium and xhigh.
Source: skill-evals.brenhq.com, updated 7 October 2026. 24 explain runs. The no-skill side is the skills test's no-skill explain runs, same day and setting.

Real app work#
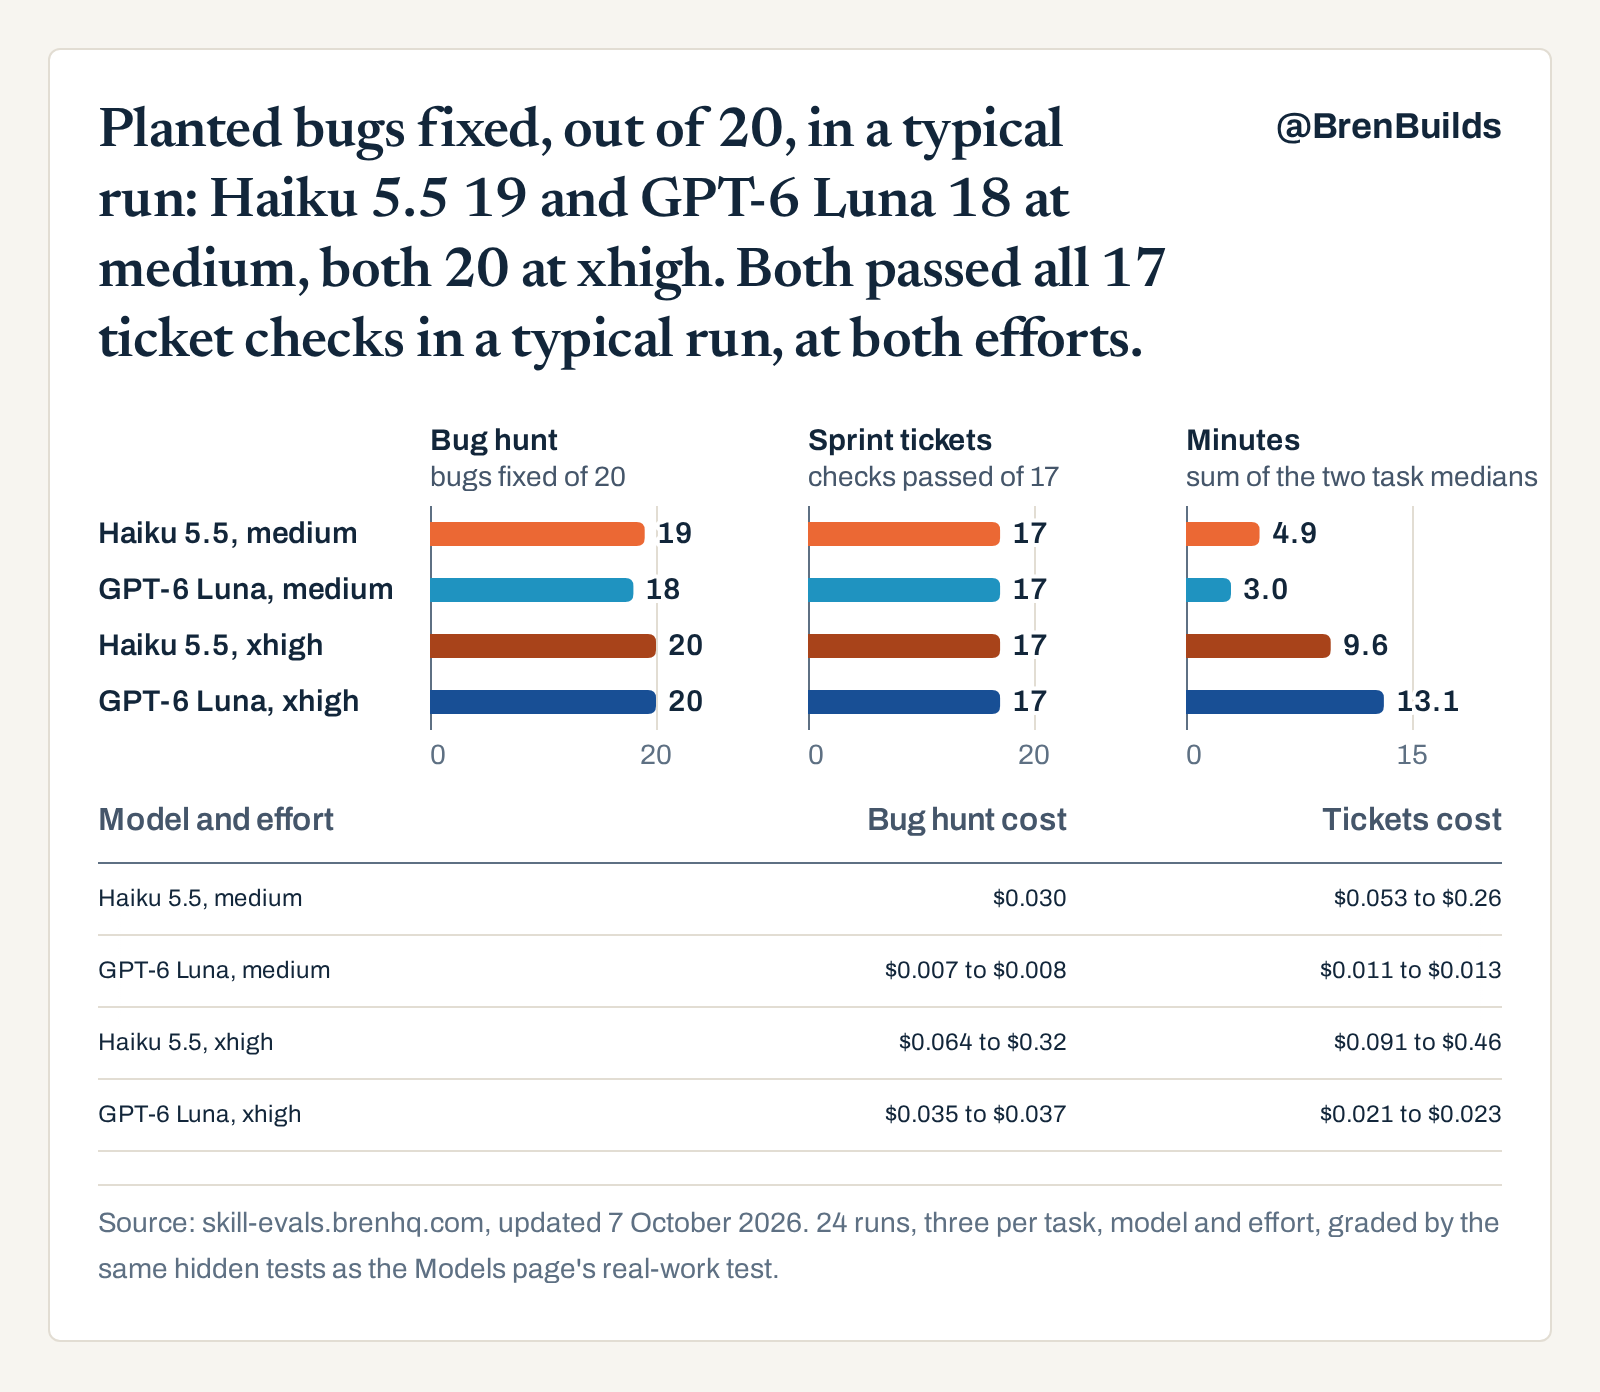
At medium, Haiku 5.5 fixed 19 of 20 planted bugs by median and GPT-6 Luna 18, and both had a median of 17 of 17 ticket checks; at xhigh, Haiku 5.5 fixed 20 of 20 planted bugs by median and GPT-6 Luna 20, and both had a median of 17 of 17 ticket checks.
A bug hunt with 20 planted bugs and three sprint tickets in a small TypeScript app, graded by hidden tests; medians of three runs. Hover or tap a row for every run.
| Model and effort | Bug hunt cost | Tickets cost |
|---|---|---|
| Haiku 5.5, medium | $0.030 | $0.053 to $0.26 |
| GPT-6 Luna, medium | $0.007 to $0.008 | $0.011 to $0.013 |
| Haiku 5.5, xhigh | $0.064 to $0.32 | $0.091 to $0.46 |
| GPT-6 Luna, xhigh | $0.035 to $0.037 | $0.021 to $0.023 |
Cost per run by median, at each vendor's list price. Some Haiku 5.5 runs' prompts passed 100k tokens, where Anthropic charges a higher rate per request; the run records keep only the last request's size, so those costs are a range from every request at the lower rate to every request at the higher one. GPT-6 Luna's are a range from its input rate to its cache-write rate for uncached prompt tokens, because Codex logs no cache writes. Below full marks on the tickets or failed: GPT-6 Luna, medium's tickets run 3 (15 of 17, marked failed). Broke something that had worked: GPT-6 Luna, medium's bug hunt run 3 (1 regression).
Source: skill-evals.brenhq.com, updated 7 October 2026. 24 runs, three per task, model and effort, graded by the same hidden tests as the Models page's real-work test.
Cost#
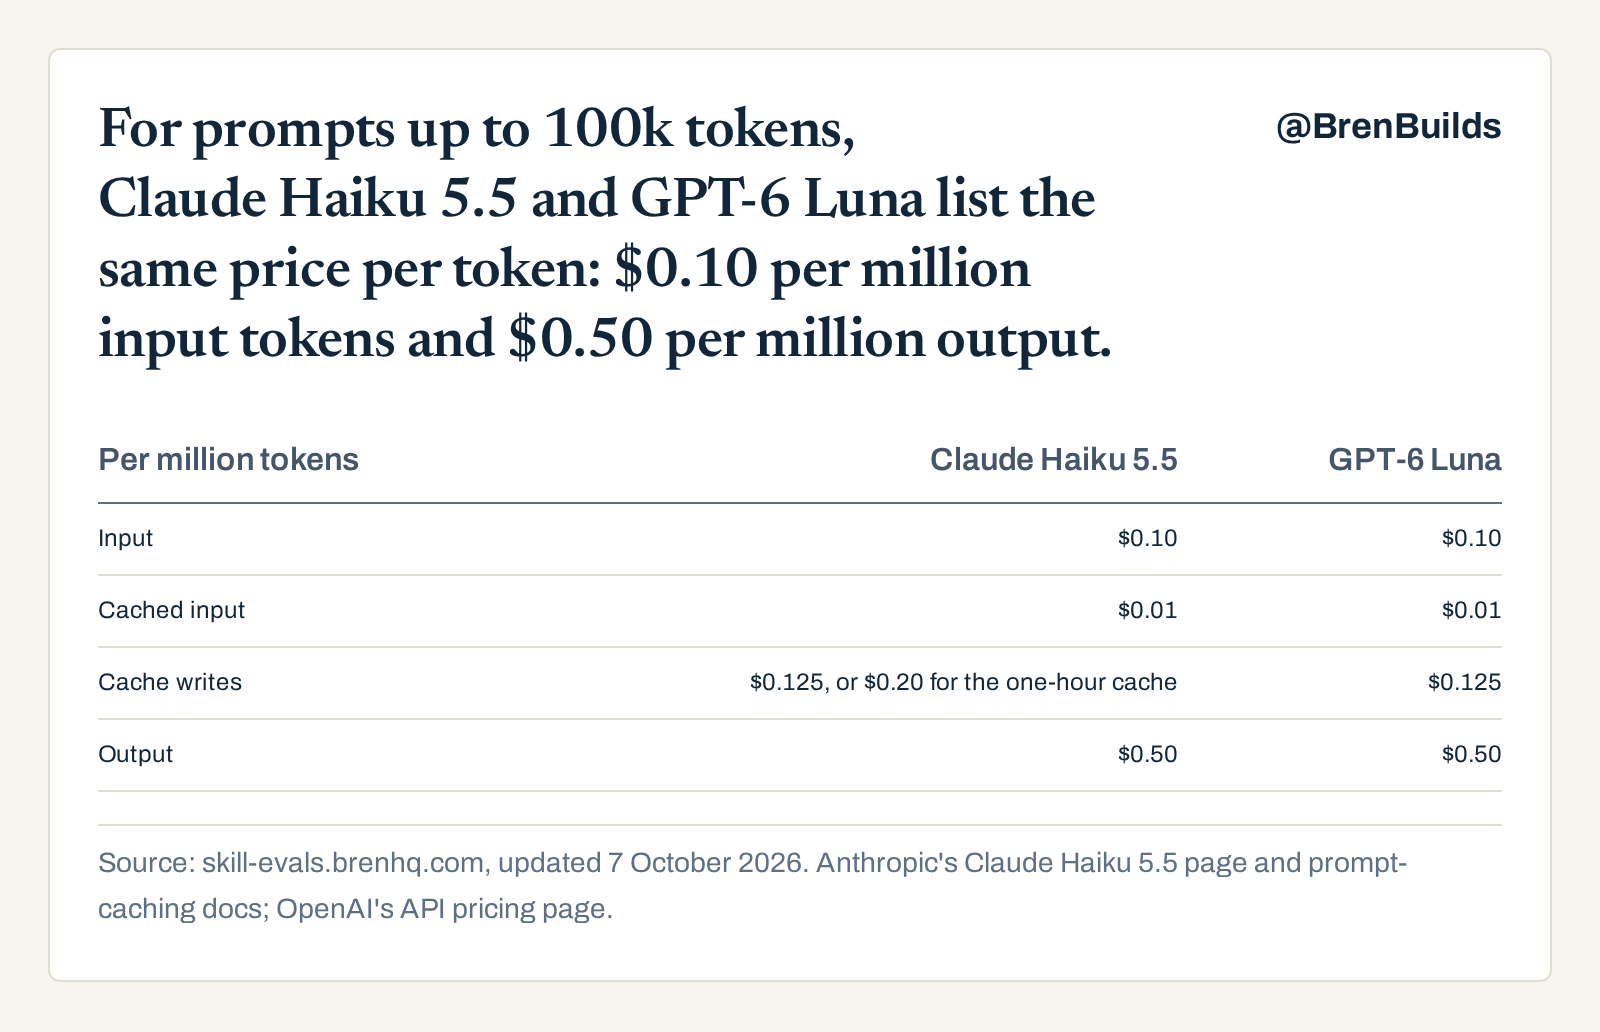
For prompts up to 100k tokens, Claude Haiku 5.5 and GPT-6 Luna list the same price per token: $0.10 per million input tokens and $0.50 per million output.
US dollars per million tokens, standard tier, as each vendor lists them.
| Per million tokens | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|
| Input | $0.10 | $0.10 |
| Cached input | $0.01 | $0.01 |
| Cache writes | $0.125, or $0.20 for the one-hour cache | $0.125 |
| Output | $0.50 | $0.50 |
Haiku 5.5's prices rise to $0.50 input and $2.50 output for a request whose prompt passes 100k tokens. Claude Code writes Anthropic's one-hour cache, at twice the input price, and the costs here include those writes. Codex logs no cache-write count, so GPT-6 Luna's costs are shown as a range: its uncached prompt tokens from the $0.10 input rate to the $0.125 cache-write rate.
Source: skill-evals.brenhq.com, updated 7 October 2026. Anthropic's Claude Haiku 5.5 page and prompt-caching docs; OpenAI's API pricing page.
How I ran it#
Background, method and definitions
Claude Haiku 5.5 ran in Claude Code 2.1.284 and GPT-6 Luna in Codex CLI 0.159.0, in the bench's Docker container with the account's apps, plugins and connectors off, at medium and at xhigh effort. Those are each tool's own settings: Claude Code's --effort and Codex's reasoning effort. Left alone, Claude Code 2.1.284 runs Haiku 5.5 at high and Codex runs GPT-6 Luna at medium, so I ran both at the same two levels. Every run is reported, failed ones included, and the plan was written down before the runs.
Claude Code 2.1.284 predates the first release that lists Haiku 5.5, 2.1.293: 2.1.284 accepts the model, but prices its runs at Opus 5.5's rates and runs it at high effort when none is set. So I reran Haiku 5.5's speed test on 2.1.293: 6.6 to 9.0 s at medium and 11.4 to 14.9 s at xhigh, against 6.4 to 7.9 s and 8.9 to 16.1 s on 2.1.284, with 503 and 1,955 thinking tokens in the answer by median against 500 and 2,087. The runs overlap and every counted run set its effort, so the 2.1.284 runs stand, though I had planned to rerun everything if the default differed, and it did: with no effort set, 2.1.293 ran Haiku 5.5 at medium, the same default Codex uses for GPT-6 Luna. Only speed was checked, so skills and real-work token counts on 2.1.293 could differ. These check runs ran while other tests were running.
The speed test is the explain task the GPT-6.1 Sol page uses: the tool reads a small Python file and explains how it adds up monthly totals and what happens with a bad date, without changing anything. The clock runs from starting the tool until it exits, one run at a time, with nothing else running, except the seventh GPT-6 Luna medium run, which replaced a failed one, and the Claude Code check below; both ran while other tests ran. A run passes when its answer contains both "month" and "ValueError".
TPS here is visible tokens a second: the answer reply's output tokens minus its hidden thinking, each vendor's own count, over the seconds from its first text event to its last, as the text reaches my machine. A rate counts only when the text arrived in at least 20 separate bursts, where text more than 5 ms after the previous text starts a new one. Text a service holds back and sends at once arrives in one or two bursts, and its rate would mean nothing. In the trial runs before the counted ones, Claude Sonnet 5.5's answers arrived in 1 and 2 bursts, which is why the GPT-6.1 Sol page has no Claude TPS, while Haiku 5.5's arrived in about a hundred. Anthropic and OpenAI count tokens differently, so a Haiku token and a Luna token are not the same amount of text.
The skills test is the Skills page's: four small tasks (explain, feature, bug fix and build), each run three times with no skill, with a placebo instruction file and with caveman, ponytail and karpathy-skills as instruction files, for both models at both efforts. The ASD-STE100 test adds Karpathy's one-line instruction to the explain task, three runs each. Costs use each vendor's list price per token for prompts up to 100k tokens. No skills run's prompt passed 100k; eight real-work runs did, and their costs show as a range there.
Changes after the runs started, each logged with its reason: one failed GPT-6 Luna medium speed run was replaced by a seventh, and speed comparisons use passed runs; GPT-6 Luna's costs became a range because Codex logs no cache writes; Haiku 5.5 runs whose prompts passed 100k tokens show a cost range because only the last request's size was kept; the X video shows the six passed GPT-6 Luna medium runs without noting the failed one, which this page and the table list; Haiku 5.5's cache writes use the one-hour rate of $0.20, the one Claude Code's requests pay; and a TPS median needs at least three runs that streamed. The plan and every change to it, as logged, are in haiku-luna-plan.txt.
The run records are in results.json, under h2h_timing_runs, h2h_runs, h2h_real_runs, h2h_cli_check and h2h_timing_smoke.