On one explain task, GPT-6.1 Sol and Gemini 4 Argon were close, and both finished ahead of Claude Opus 5.5.
Gemini 4 Argon launched in Cursor on 13 October. I ran it through my launch suite that day in Cursor CLI, beside Claude Opus 5.5 in Claude Code and GPT-6.1 Sol in Codex CLI.
Speed#
On one explain task, GPT-6.1 Sol and Gemini 4 Argon were close, and both finished ahead of Claude Opus 5.5. A typical run: GPT-6.1 Sol 10.6 s, Gemini 4 Argon 11.4 s, Claude Opus 5.5 15.9 s.
The same explain task, start to finish, the three models taking turns in one sitting. Hover or tap a row for every run.
| Model | Tool | Run 1 | Run 2 | Run 3 | Run 4 | Run 5 | Run 6 |
|---|---|---|---|---|---|---|---|
| Gemini 4 Argon | Cursor CLI | 31.7 s | 11.3 s | 11.6 s | 11.0 s | 10.1 s | 11.7 s |
| Claude Opus 5.5 | Claude Code | 17.2 s | 16.5 s | 15.7 s | 13.8 s | 16.1 s | 11.5 s |
| GPT-6.1 Sol | Codex CLI | 14.7 s | 9.5 s | 10.8 s | 10.4 s | 11.5 s | 10.3 s |
The table scrolls sideways on a small screen.
Source: skill-evals.brenhq.com, updated 13 October 2026. 18 runs, six per model, medium effort, each in its own tool.
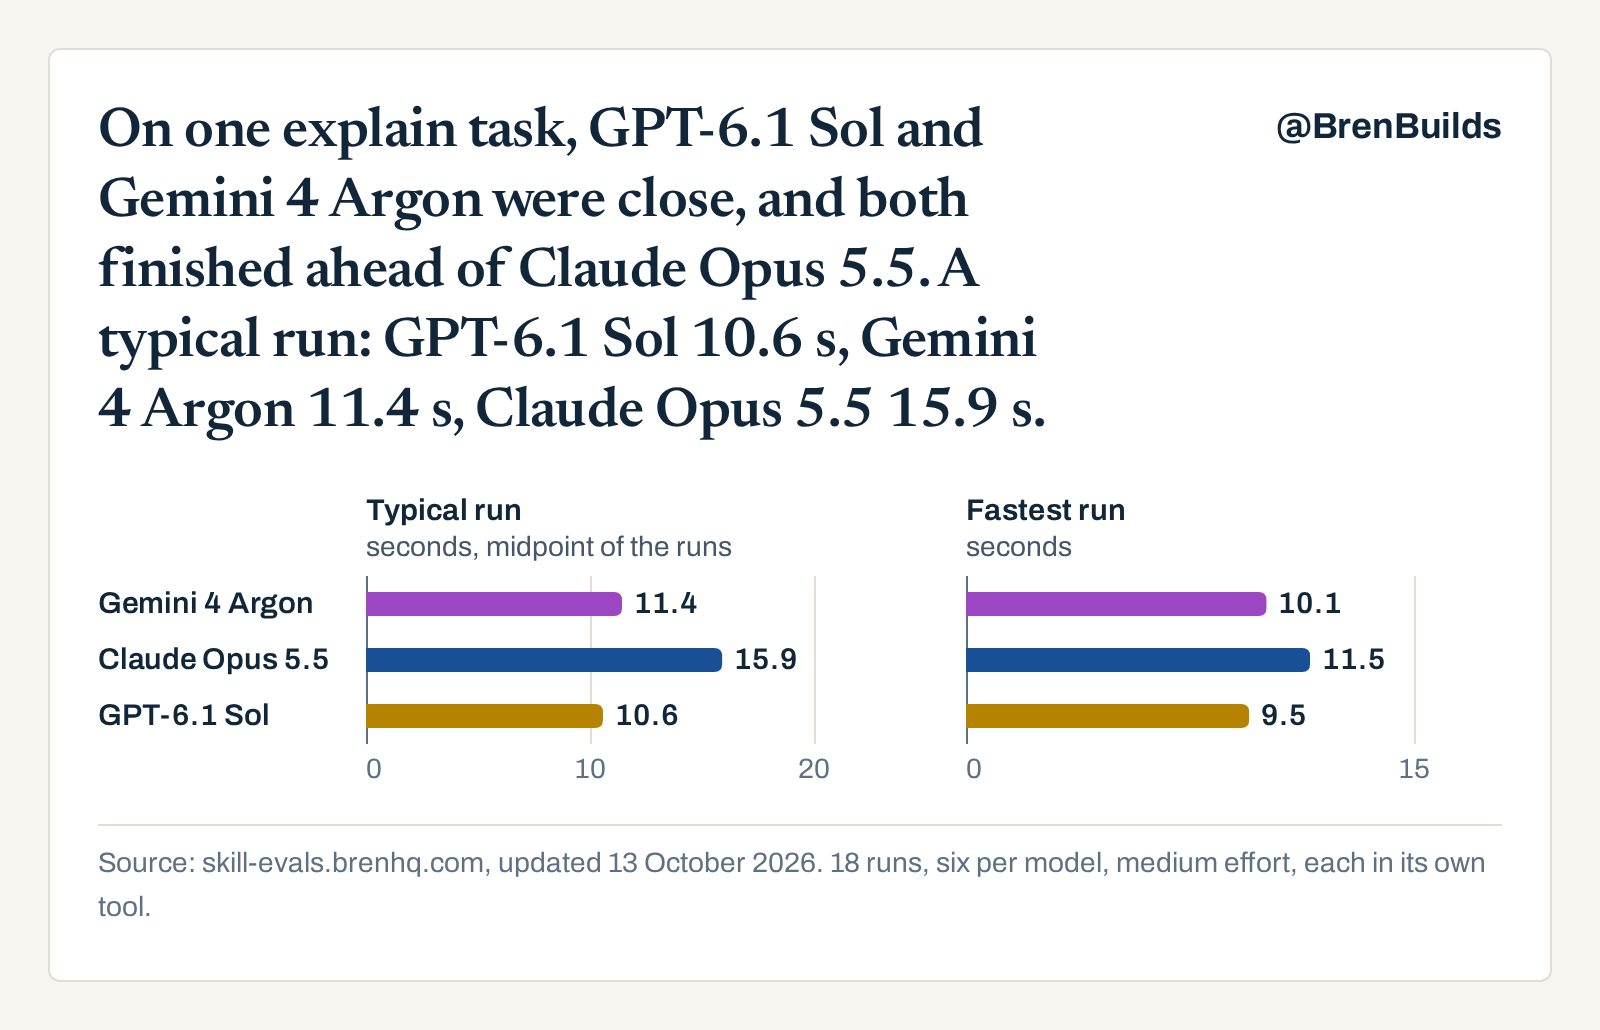
The race#
- Gemini 4 Argon: 10.1 to 31.7 s
- Claude Opus 5.5: 11.5 to 17.2 s
- GPT-6.1 Sol: 9.5 to 14.7 s
Every check#
Each launch-suite check, run the same way for all three. Every model passed nearly all of them, so this suite cannot rank them.
| Check | Gemini 4 Argon | Claude Opus 5.5 | GPT-6.1 Sol |
|---|---|---|---|
| Four small coding tasks, every setup: runs that passed | 60 of 60 | 60 of 60 | 60 of 60 |
| ASD-STE100 instruction on the explain task: runs that passed | 3 of 3 | 3 of 3 | 3 of 3 |
| Bug hunt: bugs fixed of 20, each run | 20, 20, 20 of 20 | 20, 20, 20 of 20 | 20, 20, 20 of 20 |
| Bug hunt: runs that edited the existing tests | 1 of 3 | 0 of 3 | 0 of 3 |
| Sprint tickets: hidden checks passed, each run | 17, 17, 17 of 17 | 17, 17, 17 of 17 | 17, 17, 17 of 17 |
The table scrolls sideways on a small screen.
Every run counts. A run that edits an existing test fails its check, whatever else it fixed; new test files are allowed. The runs are from Gemini 4 Argon 13 October, Claude Opus 5.5 22 to 30 September and GPT-6.1 Sol 29 to 30 September, all in 2026, each in its own tool.
How I ran it#
Background and method
Gemini 4 Argon ran in Cursor CLI (2026.10.01-e373342) as Cursor's medium variant, Claude Opus 5.5 in Claude Code 2.1.284 and GPT-6.1 Sol in Codex CLI 0.159.0, all at medium effort, in the bench's Docker container on my own subscriptions, with no API key. The tool is part of what is measured: these are three models in three tools.
Speed is the explain task the other pages use: the tool reads a small Python file and explains it, timed from starting the tool until it exits. The three models took turns, six runs each, while other tests ran on the same machine, so these seconds are not compared with other days. A run passes when its answer names both the month logic and the ValueError. Cursor does not report when a request leaves or streams its answer word by word, so this page has no tokens-per-second figure. An earlier sitting the same day with only Gemini 4 Argon and GPT-6.1 Sol gave 12.2 s (10.8 s to 47.0 s) and 12.7 s (10.6 s to 15.9 s).
The checks are the launch suite: four small coding tasks with no skill, a placebo instruction file and three token-saving skills, three runs each; Karpathy's ASD-STE100 instruction on the explain task; and real app work, a bug hunt with 20 planted bugs and three sprint tickets in a small TypeScript app, graded afterwards by hidden tests. Claude Opus 5.5's and GPT-6.1 Sol's checks are their published runs of the same tasks.
The run records are in results.json, under launch27_timing (sitting "3way" is this page's speed result, "pair" the earlier one), launch27_runs and launch27_real_runs, with Opus 5.5's and GPT-6.1 Sol's under runs, ste_runs and bughunt_runs.