Claude Opus 5.5, GPT-6.1 Sol and Claude Haiku 5.5 were within one run of each other on hard coding tasks.
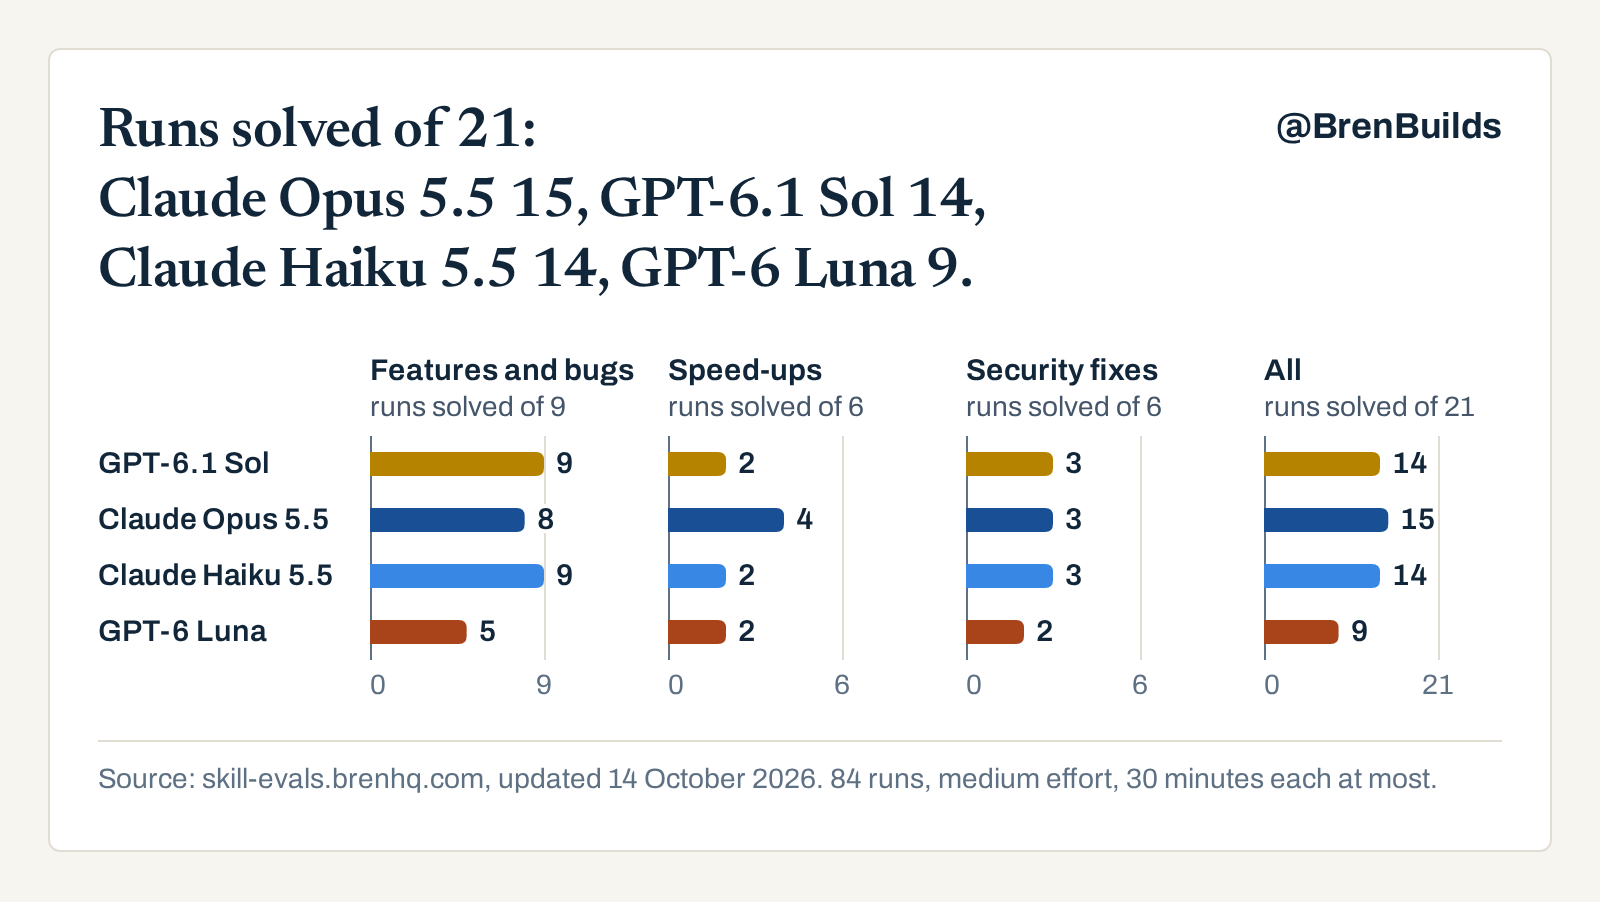
A run is one fresh try at a task, 30 minutes at most, graded by the task's own tests. Each model had three runs at each of seven tasks: Claude Opus 5.5 solved 15 of its 21 runs, GPT-6.1 Sol and Claude Haiku 5.5 14 each, and GPT-6 Luna 9. They are public tasks in real open-source projects: building features, fixing bugs, speeding up code and fixing memory-safety flaws in C. One more task, Ansible, is reported on its own and left out of these totals.
Runs solved#
Each task had three runs per model, so a gap of one run can come from chance alone. The panels split the count by kind of work.
Runs solved of 21: Claude Opus 5.5 15, GPT-6.1 Sol 14, Claude Haiku 5.5 14, GPT-6 Luna 9.
Seven public tasks in real open-source projects, three runs each, graded by each task's own tests. Hover or tap a row for every task.
Source: skill-evals.brenhq.com, updated 14 October 2026. 84 runs, medium effort, 30 minutes each at most.
Every task#
Every model got the same task text in the same container, three runs per task, with no web access and 30 minutes per run at most. Each square is one run: solved, not solved.
| Task | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Build a featureThe model gets a feature request. A run passes when the project's tests for that feature, which the model never sees, pass and its existing tests still pass. | ||||
| Flipt feature-flag server, GoLet one rule target several user segments at once. | 3 of 3 | 3 of 3 | 3 of 3 | 1 of 3 |
| Fix a bugThe model gets a bug report. A run passes when the project's tests for that bug, which the model never sees, pass and its existing tests still pass. | ||||
| Proton Mail web client email web app, TypeScriptHold back mailbox reloads until pending changes finish, and recover from failed loads. | 3 of 3 | 2 of 3 | 3 of 3 | 1 of 3 |
| Navidrome music streaming server, GoFix pages that crash after an upgrade leaves date fields empty. | 3 of 3 | 3 of 3 | 3 of 3 | 3 of 3 |
| Speed up codeThe model gets a script that times a slow operation. A run passes when the results are unchanged, the code is at least 1.1 times as fast, and it reaches 95% of the speed-up the project's own developer got. | ||||
| pandas data library, PythonMake setting values one at a time in nullable integer arrays faster. | 0 of 3 | 1 of 3 | 0 of 3 | 0 of 3 |
| NumPy math library, PythonMake np.isin faster on integer arrays. | 2 of 3 | 3 of 3 | 2 of 3 | 2 of 3 |
| Fix a security flawThe model gets a memory checker's crash report. A run passes only when the crash is gone and the library's own tests and checks still pass. | ||||
| wolfSSL TLS and crypto library, CFix a heap buffer overflow when a big number is written out in hex. | 3 of 3 | 3 of 3 | 3 of 3 | 2 of 3 |
| LibreDWG library that reads CAD drawings, CFix a buffer over-read while reading a drawing file. | 0 of 3 | 0 of 3 | 0 of 3 | 0 of 3 |
| Reported on its ownLeft out of every total: its hidden tests need a get_manager() method that the task text never names. | ||||
| Ansible IT automation tool, PythonAdd a module that manages message routing routes on F5 BIG-IP devices. | 2 of 3 | 3 of 3 | 1 of 3 | 0 of 3 |
Every run
| Task | Model | Run | Solved | Minutes | Output tokens | Upstream lines | What the grader saw |
|---|---|---|---|---|---|---|---|
| Ansible | GPT-6.1 Sol | 1 | yes | 2.6 | 5,971 | 41% | 6 of 6 hidden tests passed |
| Ansible | GPT-6.1 Sol | 2 | yes | 3.1 | 7,057 | 39% | 6 of 6 hidden tests passed |
| Ansible | GPT-6.1 Sol | 3 | no | 2.4 | 6,040 | 42% | 3 of 6 hidden tests passed |
| Ansible | Claude Opus 5.5 | 1 | yes | 1.9 | 11,227 | 91% * | 6 of 6 hidden tests passed |
| Ansible | Claude Opus 5.5 | 2 | yes | 2.0 | 13,528 | 91% * | 6 of 6 hidden tests passed |
| Ansible | Claude Opus 5.5 | 3 | yes | 1.8 | 11,393 | 92% * | 6 of 6 hidden tests passed |
| Ansible | Claude Haiku 5.5 | 1 | no | 1.1 | 15,573 | 74% * | 3 of 6 hidden tests passed |
| Ansible | Claude Haiku 5.5 | 2 | yes | 1.2 | 15,798 | 72% * | 6 of 6 hidden tests passed |
| Ansible | Claude Haiku 5.5 | 3 | no | 1.5 | 17,767 | 73% * | 3 of 6 hidden tests passed |
| Ansible | GPT-6 Luna | 1 | no | 0.6 | 3,486 | 29% | 3 of 6 hidden tests passed |
| Ansible | GPT-6 Luna | 2 | no | 0.7 | 4,115 | 24% | 3 of 6 hidden tests passed |
| Ansible | GPT-6 Luna | 3 | no | 1.2 | 3,419 | 22% | 3 of 6 hidden tests passed |
| Flipt | GPT-6.1 Sol | 1 | yes | 4.4 | 8,219 | 9% | 3 of 3 hidden tests passed |
| Flipt | GPT-6.1 Sol | 2 | yes | 4.0 | 7,448 | 9% | 3 of 3 hidden tests passed |
| Flipt | GPT-6.1 Sol | 3 | yes | 4.1 | 8,634 | 16% | 3 of 3 hidden tests passed |
| Flipt | Claude Opus 5.5 | 1 | yes | 5.1 | 12,383 | 71% * | 3 of 3 hidden tests passed |
| Flipt | Claude Opus 5.5 | 2 | yes | 4.0 | 10,782 | 85% * | 3 of 3 hidden tests passed |
| Flipt | Claude Opus 5.5 | 3 | yes | 4.4 | 11,544 | 76% * | 3 of 3 hidden tests passed |
| Flipt | Claude Haiku 5.5 | 1 | yes | 3.1 | 21,393 | 26% | 3 of 3 hidden tests passed |
| Flipt | Claude Haiku 5.5 | 2 | yes | 4.1 | 19,712 | 24% | 3 of 3 hidden tests passed |
| Flipt | Claude Haiku 5.5 | 3 | yes | 3.3 | 18,353 | 20% | 3 of 3 hidden tests passed |
| Flipt | GPT-6 Luna | 1 | yes | 1.1 | 4,157 | 0% | 3 of 3 hidden tests passed |
| Flipt | GPT-6 Luna | 2 | no | 2.5 | 5,358 | 6% | 2 of 3 hidden tests passed |
| Flipt | GPT-6 Luna | 3 | no | 1.5 | 3,731 | 3% | 2 of 3 hidden tests passed |
| Proton Mail web client | GPT-6.1 Sol | 1 | yes | 6.0 | 10,560 | 56% | 3 of 3 hidden tests passed |
| Proton Mail web client | GPT-6.1 Sol | 2 | yes | 7.0 | 13,757 | 57% | 3 of 3 hidden tests passed |
| Proton Mail web client | GPT-6.1 Sol | 3 | yes | 7.9 | 13,238 | 57% | 3 of 3 hidden tests passed |
| Proton Mail web client | Claude Opus 5.5 | 1 | yes | 18.1 | 18,378 | 70% * | 3 of 3 hidden tests passed |
| Proton Mail web client | Claude Opus 5.5 | 2 | yes | 13.0 | 17,007 | 68% * | 3 of 3 hidden tests passed |
| Proton Mail web client | Claude Opus 5.5 | 3 | no | 18.2 | 13,324 | 70% * | 2 of 3 hidden tests passed |
| Proton Mail web client | Claude Haiku 5.5 | 1 | yes | 10.7 | 44,202 | 61% * | 3 of 3 hidden tests passed |
| Proton Mail web client | Claude Haiku 5.5 | 2 | yes | 8.1 | 55,829 | 56% | 3 of 3 hidden tests passed |
| Proton Mail web client | Claude Haiku 5.5 | 3 | yes | 5.8 | 41,899 | 64% * | 3 of 3 hidden tests passed |
| Proton Mail web client | GPT-6 Luna | 1 | yes | 1.3 | 5,382 | 43% | 3 of 3 hidden tests passed |
| Proton Mail web client | GPT-6 Luna | 2 | no | 1.2 | 3,458 | 42% | 2 of 3 hidden tests passed |
| Proton Mail web client | GPT-6 Luna | 3 | no | 0.9 | 3,728 | 42% | 2 of 3 hidden tests passed |
| Navidrome | GPT-6.1 Sol | 1 | yes | 2.7 | 5,394 | 12% | 3 of 3 hidden tests passed |
| Navidrome | GPT-6.1 Sol | 2 | yes | 2.7 | 5,287 | 12% | 3 of 3 hidden tests passed |
| Navidrome | GPT-6.1 Sol | 3 | yes | 1.7 | 3,304 | 12% | 3 of 3 hidden tests passed |
| Navidrome | Claude Opus 5.5 | 1 | yes | 1.6 | 3,774 | 12% | 3 of 3 hidden tests passed |
| Navidrome | Claude Opus 5.5 | 2 | yes | 1.6 | 3,812 | 12% | 3 of 3 hidden tests passed |
| Navidrome | Claude Opus 5.5 | 3 | yes | 1.6 | 3,284 | 12% | 3 of 3 hidden tests passed |
| Navidrome | Claude Haiku 5.5 | 1 | yes | 1.5 | 7,543 | 12% | 3 of 3 hidden tests passed |
| Navidrome | Claude Haiku 5.5 | 2 | yes | 2.0 | 9,813 | 12% | 3 of 3 hidden tests passed |
| Navidrome | Claude Haiku 5.5 | 3 | yes | 1.4 | 5,988 | 12% | 3 of 3 hidden tests passed |
| Navidrome | GPT-6 Luna | 1 | yes | 0.9 | 3,518 | 1% | 3 of 3 hidden tests passed |
| Navidrome | GPT-6 Luna | 2 | yes | 0.6 | 2,795 | 2% | 3 of 3 hidden tests passed |
| Navidrome | GPT-6 Luna | 3 | yes | 1.3 | 3,201 | 1% | 3 of 3 hidden tests passed |
| pandas | GPT-6.1 Sol | 1 | no | 2.5 | 4,686 | 11% | 1.16x faster than before; 0.435 of the expert's speed-up |
| pandas | GPT-6.1 Sol | 2 | no | 3.5 | 5,705 | 4% | 1.17x faster than before; 0.446 of the expert's speed-up |
| pandas | GPT-6.1 Sol | 3 | no | 3.3 | 5,764 | 11% | 1.19x faster than before; 0.441 of the expert's speed-up |
| pandas | Claude Opus 5.5 | 1 | yes | 2.0 | 9,197 | 21% | 2.56x faster than before; 1.032 of the expert's speed-up |
| pandas | Claude Opus 5.5 | 2 | no | 1.9 | 7,848 | 14% | 1.86x faster than before; 0.746 of the expert's speed-up |
| pandas | Claude Opus 5.5 | 3 | no | 1.9 | 6,919 | 11% | 1.88x faster than before; 0.751 of the expert's speed-up |
| pandas | Claude Haiku 5.5 | 1 | no | 1.6 | 8,975 | 7% | 1.14x faster than before; 0.429 of the expert's speed-up |
| pandas | Claude Haiku 5.5 | 2 | no | 3.7 | 11,009 | 11% | 1.25x faster than before; 0.452 of the expert's speed-up |
| pandas | Claude Haiku 5.5 | 3 | no | 1.2 | 12,206 | 7% | 1.15x faster than before; 0.429 of the expert's speed-up |
| pandas | GPT-6 Luna | 1 | no | 1.2 | 3,707 | 7% | 1.15x faster than before; 0.431 of the expert's speed-up |
| pandas | GPT-6 Luna | 2 | no | 1.5 | 4,971 | 7% | 1.23x faster than before; 0.455 of the expert's speed-up |
| pandas | GPT-6 Luna | 3 | no | 1.2 | 3,063 | 7% | 1.12x faster than before; 0.427 of the expert's speed-up |
| NumPy | GPT-6.1 Sol | 1 | yes | 4.7 | 7,829 | 4% | 7.50x faster than before; 1.039 of the expert's speed-up |
| NumPy | GPT-6.1 Sol | 2 | no | 2.6 | 4,288 | 0% | 6.89x faster than before; 0.934 of the expert's speed-up |
| NumPy | GPT-6.1 Sol | 3 | yes | 2.5 | 4,273 | 0% | 6.68x faster than before; 0.950 of the expert's speed-up |
| NumPy | Claude Opus 5.5 | 1 | yes | 2.5 | 10,320 | 0% | 9.67x faster than before; 1.234 of the expert's speed-up |
| NumPy | Claude Opus 5.5 | 2 | yes | 1.4 | 6,985 | 4% | 9.54x faster than before; 1.185 of the expert's speed-up |
| NumPy | Claude Opus 5.5 | 3 | yes | 1.9 | 10,109 | 0% | 11.84x faster than before; 1.457 of the expert's speed-up |
| NumPy | Claude Haiku 5.5 | 1 | no | 1.5 | 14,236 | 0% | 1.72x faster than before; 0.181 of the expert's speed-up |
| NumPy | Claude Haiku 5.5 | 2 | yes | 3.4 | 17,170 | 0% | 7.69x faster than before; 1.050 of the expert's speed-up |
| NumPy | Claude Haiku 5.5 | 3 | yes | 1.6 | 15,219 | 0% | 8.94x faster than before; 1.093 of the expert's speed-up |
| NumPy | GPT-6 Luna | 1 | yes | 1.2 | 2,628 | 0% | 11.18x faster than before; 1.292 of the expert's speed-up |
| NumPy | GPT-6 Luna | 2 | no | 0.8 | 2,528 | 0% | 6.46x faster than before; 0.779 of the expert's speed-up |
| NumPy | GPT-6 Luna | 3 | yes | 1.0 | 2,843 | 0% | 11.90x faster than before; 1.522 of the expert's speed-up |
| wolfSSL | GPT-6.1 Sol | 1 | yes | 5.4 | 4,337 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| wolfSSL | GPT-6.1 Sol | 2 | yes | 4.8 | 3,009 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| wolfSSL | GPT-6.1 Sol | 3 | yes | 6.8 | 3,039 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| wolfSSL | Claude Opus 5.5 | 1 | yes | 30.1 (cap) | – | 100% * | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| wolfSSL | Claude Opus 5.5 | 2 | yes | 9.2 | 2,262 | 100% * | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| wolfSSL | Claude Opus 5.5 | 3 | yes | 9.2 | 2,424 | 100% * | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| wolfSSL | Claude Haiku 5.5 | 1 | yes | 4.1 | 10,932 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| wolfSSL | Claude Haiku 5.5 | 2 | yes | 16.6 | 24,647 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| wolfSSL | Claude Haiku 5.5 | 3 | yes | 14.3 | 25,326 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| wolfSSL | GPT-6 Luna | 1 | yes | 7.0 | 5,699 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| wolfSSL | GPT-6 Luna | 2 | no | 4.0 | 3,615 | 0% | crash input fixed: no; replayed inputs: no; unit tests: yes; output match: yes |
| wolfSSL | GPT-6 Luna | 3 | yes | 3.3 | 4,248 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: yes; output match: yes |
| LibreDWG | GPT-6.1 Sol | 1 | no | 7.1 | 3,146 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: no; output match: no |
| LibreDWG | GPT-6.1 Sol | 2 | no | 9.6 | 3,649 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: no; output match: no |
| LibreDWG | GPT-6.1 Sol | 3 | no | 10.7 | 3,818 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: no; output match: no |
| LibreDWG | Claude Opus 5.5 | 1 | no | 15.0 | 5,938 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: no; output match: no |
| LibreDWG | Claude Opus 5.5 | 2 | no | 17.7 | 9,492 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: no; output match: no |
| LibreDWG | Claude Opus 5.5 | 3 | no | 15.6 | 8,026 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: no; output match: no |
| LibreDWG | Claude Haiku 5.5 | 1 | no | 13.4 | 9,366 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: no; output match: no |
| LibreDWG | Claude Haiku 5.5 | 2 | no | 17.9 | 38,108 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: no; output match: no |
| LibreDWG | Claude Haiku 5.5 | 3 | no | 21.1 | 15,374 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: no; output match: no |
| LibreDWG | GPT-6 Luna | 1 | no | 13.2 | 8,460 | 0% | crash input fixed: no; replayed inputs: no; unit tests: no; output match: no |
| LibreDWG | GPT-6 Luna | 2 | no | 6.8 | 2,838 | 0% | crash input fixed: no; replayed inputs: no; unit tests: no; output match: no |
| LibreDWG | GPT-6 Luna | 3 | no | 16.6 | 6,279 | 0% | crash input fixed: yes; replayed inputs: yes; unit tests: no; output match: no |
The table scrolls sideways on a small screen.
Upstream lines is the share of the lines the project's own fix added (outside tests, spacing ignored, lines under 12 characters left out) that also appear among the lines the run added. These are public tasks, so a model may have seen that fix in training; at 60% or more a run is marked *, a warning rather than proof: a project's own conventions can produce the same lines, and a fix of a line or two can match by nature. I set that mark after seeing the first runs. Marked: Claude Haiku 5.5 on Ansible, run 1 (74%, not solved), Claude Haiku 5.5 on Ansible, run 2 (72%, solved), Claude Haiku 5.5 on Ansible, run 3 (73%, not solved), Claude Opus 5.5 on Ansible, run 1 (91%, solved), Claude Opus 5.5 on Ansible, run 2 (91%, solved), Claude Opus 5.5 on Ansible, run 3 (92%, solved), Claude Opus 5.5 on Flipt, run 1 (71%, solved), Claude Opus 5.5 on Flipt, run 2 (85%, solved), Claude Opus 5.5 on Flipt, run 3 (76%, solved), Claude Haiku 5.5 on Proton Mail web client, run 1 (61%, solved), Claude Haiku 5.5 on Proton Mail web client, run 3 (64%, solved), Claude Opus 5.5 on Proton Mail web client, run 1 (70%, solved), Claude Opus 5.5 on Proton Mail web client, run 2 (68%, solved), Claude Opus 5.5 on Proton Mail web client, run 3 (70%, not solved), Claude Opus 5.5 on wolfSSL, run 1 (100%, solved), Claude Opus 5.5 on wolfSSL, run 2 (100%, solved) and Claude Opus 5.5 on wolfSSL, run 3 (100%, solved).
Speed-ups#
How much faster each run made the code, against the expert's own change.
| Task | Model | Run | Speed-up | Of the expert's | Solved |
|---|---|---|---|---|---|
| pandas | GPT-6.1 Sol | 1 | 1.16x | 0.435 | no |
| pandas | GPT-6.1 Sol | 2 | 1.17x | 0.446 | no |
| pandas | GPT-6.1 Sol | 3 | 1.19x | 0.441 | no |
| pandas | Claude Opus 5.5 | 1 | 2.56x | 1.032 | yes |
| pandas | Claude Opus 5.5 | 2 | 1.86x | 0.746 | no |
| pandas | Claude Opus 5.5 | 3 | 1.88x | 0.751 | no |
| pandas | Claude Haiku 5.5 | 1 | 1.14x | 0.429 | no |
| pandas | Claude Haiku 5.5 | 2 | 1.25x | 0.452 | no |
| pandas | Claude Haiku 5.5 | 3 | 1.15x | 0.429 | no |
| pandas | GPT-6 Luna | 1 | 1.15x | 0.431 | no |
| pandas | GPT-6 Luna | 2 | 1.23x | 0.455 | no |
| pandas | GPT-6 Luna | 3 | 1.12x | 0.427 | no |
| NumPy | GPT-6.1 Sol | 1 | 7.50x | 1.039 | yes |
| NumPy | GPT-6.1 Sol | 2 | 6.89x | 0.934 | no |
| NumPy | GPT-6.1 Sol | 3 | 6.68x | 0.950 | yes |
| NumPy | Claude Opus 5.5 | 1 | 9.67x | 1.234 | yes |
| NumPy | Claude Opus 5.5 | 2 | 9.54x | 1.185 | yes |
| NumPy | Claude Opus 5.5 | 3 | 11.84x | 1.457 | yes |
| NumPy | Claude Haiku 5.5 | 1 | 1.72x | 0.181 | no |
| NumPy | Claude Haiku 5.5 | 2 | 7.69x | 1.050 | yes |
| NumPy | Claude Haiku 5.5 | 3 | 8.94x | 1.093 | yes |
| NumPy | GPT-6 Luna | 1 | 11.18x | 1.292 | yes |
| NumPy | GPT-6 Luna | 2 | 6.46x | 0.779 | no |
| NumPy | GPT-6 Luna | 3 | 11.90x | 1.522 | yes |
The table scrolls sideways on a small screen.
Speed-up is the run's build against the code before it, over the task's own performance tests. A run counts as solved when its outputs match, it is at least 1.1 times as fast as the code before it, and it reaches at least 0.95 of the expert commit's speed-up. In the task checks before any run, the expert's own change measured 1.006 and 1.009 of itself, so timing noise is about 1%. GPT-6.1 Sol's run 3 on NumPy (0.950) is within that noise of the bar; the grader's score stands.
Security fixes#
Which of the four security checks each run passed. No run solved LibreDWG. Ten of its 12 runs stopped the original crash; GPT-6 Luna's run 1 and GPT-6 Luna's run 2 did not. Every run failed the unit-test and output checks. The task's reference fix corrects an off-by-one in the library's bit reader (src/bits.c); the code before that fix fails one unit test that the fix passes. No run changed the bit reader.
| Task | Model | Run | Crash input | Replayed inputs | Unit tests | Output match | Solved |
|---|---|---|---|---|---|---|---|
| wolfSSL | GPT-6.1 Sol | 1 | yes | yes | yes | yes | yes |
| wolfSSL | GPT-6.1 Sol | 2 | yes | yes | yes | yes | yes |
| wolfSSL | GPT-6.1 Sol | 3 | yes | yes | yes | yes | yes |
| wolfSSL | Claude Opus 5.5 | 1 | yes | yes | yes | yes | yes |
| wolfSSL | Claude Opus 5.5 | 2 | yes | yes | yes | yes | yes |
| wolfSSL | Claude Opus 5.5 | 3 | yes | yes | yes | yes | yes |
| wolfSSL | Claude Haiku 5.5 | 1 | yes | yes | yes | yes | yes |
| wolfSSL | Claude Haiku 5.5 | 2 | yes | yes | yes | yes | yes |
| wolfSSL | Claude Haiku 5.5 | 3 | yes | yes | yes | yes | yes |
| wolfSSL | GPT-6 Luna | 1 | yes | yes | yes | yes | yes |
| wolfSSL | GPT-6 Luna | 2 | no | no | yes | yes | no |
| wolfSSL | GPT-6 Luna | 3 | yes | yes | yes | yes | yes |
| LibreDWG | GPT-6.1 Sol | 1 | yes | yes | no | no | no |
| LibreDWG | GPT-6.1 Sol | 2 | yes | yes | no | no | no |
| LibreDWG | GPT-6.1 Sol | 3 | yes | yes | no | no | no |
| LibreDWG | Claude Opus 5.5 | 1 | yes | yes | no | no | no |
| LibreDWG | Claude Opus 5.5 | 2 | yes | yes | no | no | no |
| LibreDWG | Claude Opus 5.5 | 3 | yes | yes | no | no | no |
| LibreDWG | Claude Haiku 5.5 | 1 | yes | yes | no | no | no |
| LibreDWG | Claude Haiku 5.5 | 2 | yes | yes | no | no | no |
| LibreDWG | Claude Haiku 5.5 | 3 | yes | yes | no | no | no |
| LibreDWG | GPT-6 Luna | 1 | no | no | no | no | no |
| LibreDWG | GPT-6 Luna | 2 | no | no | no | no | no |
| LibreDWG | GPT-6 Luna | 3 | yes | yes | no | no | no |
The table scrolls sideways on a small screen.
The four checks, each run on a fresh build with the change applied: the input that crashed it no longer crashes; no input in the task's collection of crashing variants or of benign inputs sets off the memory checker; every unit test that passes with the reference fix still passes; and output on benign inputs matches the reference fix byte for byte. A run is solved only when all four pass.
How I ran it#
Tasks, setup and grading
Why a deep suite: my launch suite, on the other pages, has every model near full marks, so it can show a model getting worse but not better. The tasks: building features and fixing bugs, speeding up Python code, and fixing memory-safety bugs in C, taken from three public task sets (credited below). Within each set the tasks were drawn in a fixed random order before any model ran, then checked: the task's own reference fix must score as solved and an unchanged repository must not. Two drawn tasks were replaced by the next in the same order: one whose reference fix failed that check here, and one that the pilot's reviewers found could only be passed by rewriting unrelated code. One drawn Go task was swapped before that because its fix needs a library the task's image does not have, and runs have no internet.
Deep suite v1, frozen 13 October 2026: these eight tasks, three runs each, with the same settings and the same container images, checked before every run. A new model runs the same set and is compared with the runs here. Changing a task, a setting or a container image makes a new version, and its scores are not compared with these.
Claude Opus 5.5 and Claude Haiku 5.5 ran in Claude Code 2.1.284, and GPT-6.1 Sol and GPT-6 Luna in Codex CLI 0.159.0, all at medium effort, each run capped at 30 minutes (1 run reached it). The original tasks allow longer. Each run worked inside the task's own container, whose only way out reached the two vendors' model servers: no web search, no package downloads and no way to look up the original fix. The run never saw the hidden tests or the reference fix; the speed-up tasks' text includes their timing script, as intended. Its change was then applied to a fresh copy of the container and graded by the task's own grader, which resets any test file the run edited. Claude Opus 5.5 and Claude Haiku 5.5 shared one login, so their runs went one at a time.
Limits: this suite cannot confirm that a model is improving week to week. It has a handful of tasks and three runs each, so a single run moves a model's count by a lot, and it measures each model inside one tool at one effort. These are public tasks, so a model may have seen the original fix in training; the run table marks runs that reproduced most of it. The speed-up tasks were picked from the ones whose expert fix changes Python only, so a rebuild fits in a run.
A pilot ran first, one run per task, and is not counted. It found bugs in my setup, each logged, with the affected runs set aside and rerun, and Fable 5.1, Grok 4.7 and GPT-6 Astra reviewed its results before these runs were made. Its runs are in the data.
The run records are in results.json, under deep_runs, deep_checks, deep_pilot_runs and deep_suite. The plan and every change to it, as logged, are in deep-suite-plan.txt.
Credit: the tasks and their graders come from SWE-bench Pro's public hard set (Scale AI), GSO and PatchBench.