Claude Opus 5.5 led on speed-up and scheduling, GPT-6.1 Sol on forecasting, and both averaged 0.98 or more on every correctness task.
Four models got two tries at each of six tasks in six languages, 20 minutes per try (10 for the job service). The three open-ended tasks split the leaders. On the three correctness tasks GPT-6.1 Sol and Claude Opus 5.5 were within 0.02 of each other, both of Claude Haiku 5.5's tries on the web app feature were invalid and GPT-6 Luna scored 0.05 to 0.54. GPT-6.1 Sol's median try took 11.3 minutes to Claude Opus 5.5's 20.1 (Opus hit the time limit on 9 of 12 tries), and Opus's estimated cost per try was 3.8 to 4.1 times Sol's at list prices.
Each version tests something different. Scores don't carry over.
Open-ended tasks#
These measure how much a try improved on where the code started, on a log2 scale, and aren't capped at my own fix's score.
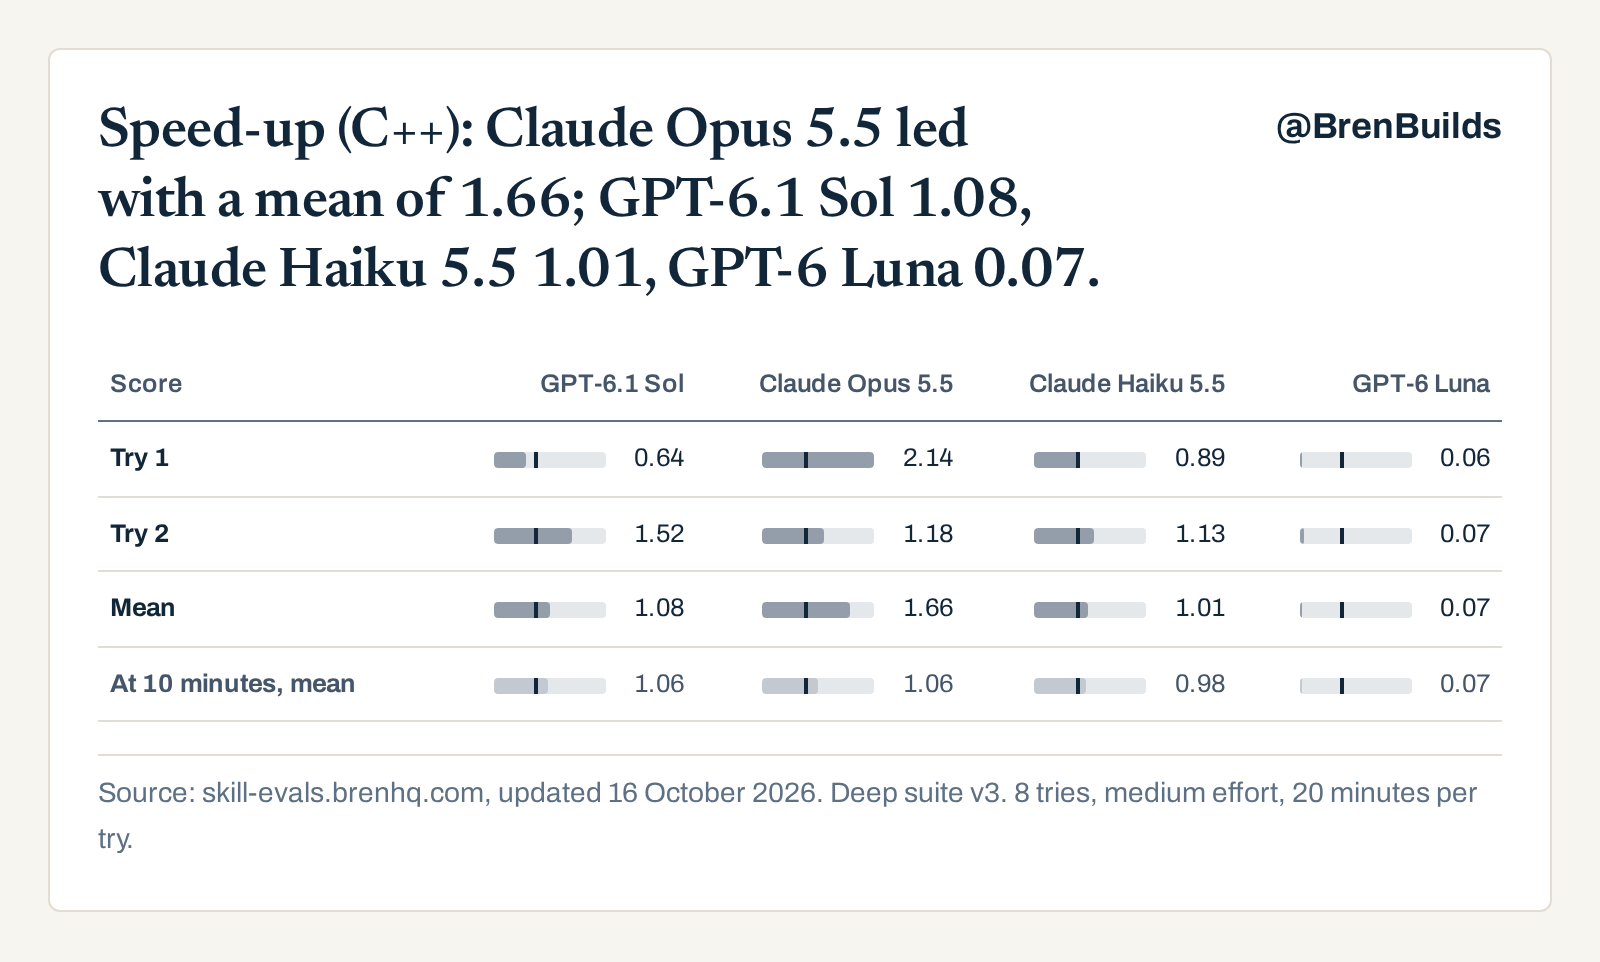
Speed-up (C++): Claude Opus 5.5 led with a mean of 1.66; GPT-6.1 Sol 1.08, Claude Haiku 5.5 1.01, GPT-6 Luna 0.07.
Make a released open-source library faster without changing its output. Times faster on a log2 scale, averaged over hidden workloads: 1 is twice as fast, 2 is four times. My own fix scored 0.82. A try that finished before 10 minutes keeps its final score at 10 minutes.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Try 1 | 0.64 | 2.14 | 0.89 | 0.06 |
| Try 2 | 1.52 | 1.18 | 1.13 | 0.07 |
| Mean | 1.08 | 1.66 | 1.01 | 0.07 |
| At 10 minutes, mean | 1.06 | 1.06 | 0.98 | 0.07 |
Source: skill-evals.brenhq.com, updated 16 October 2026. Deep suite v3. 8 tries, medium effort, 20 minutes per try.
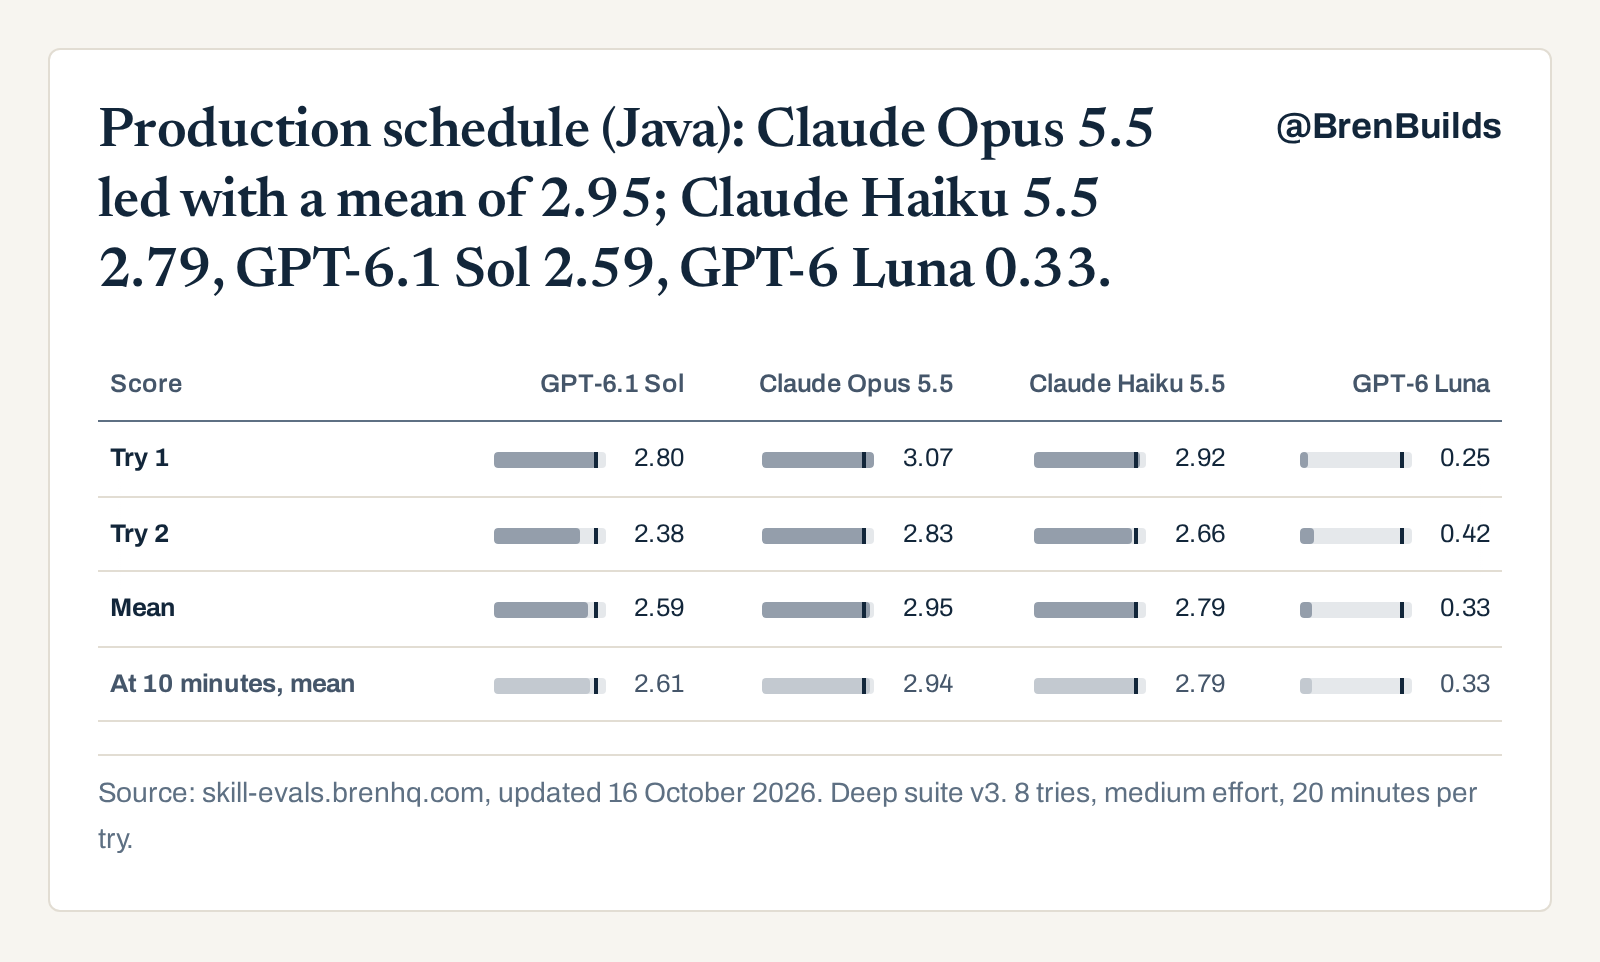
Production schedule (Java): Claude Opus 5.5 led with a mean of 2.95; Claude Haiku 5.5 2.79, GPT-6.1 Sol 2.59, GPT-6 Luna 0.33.
Make our own production planner's schedules less late, keeping every rule. How much lateness shrank against the current planner, log2, averaged over hidden cases: 1 is about half the lateness. My own fix scored 2.80. A try that finished before 10 minutes keeps its final score at 10 minutes.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Try 1 | 2.80 | 3.07 | 2.92 | 0.25 |
| Try 2 | 2.38 | 2.83 | 2.66 | 0.42 |
| Mean | 2.59 | 2.95 | 2.79 | 0.33 |
| At 10 minutes, mean | 2.61 | 2.94 | 2.79 | 0.33 |
Source: skill-evals.brenhq.com, updated 16 October 2026. Deep suite v3. 8 tries, medium effort, 20 minutes per try.
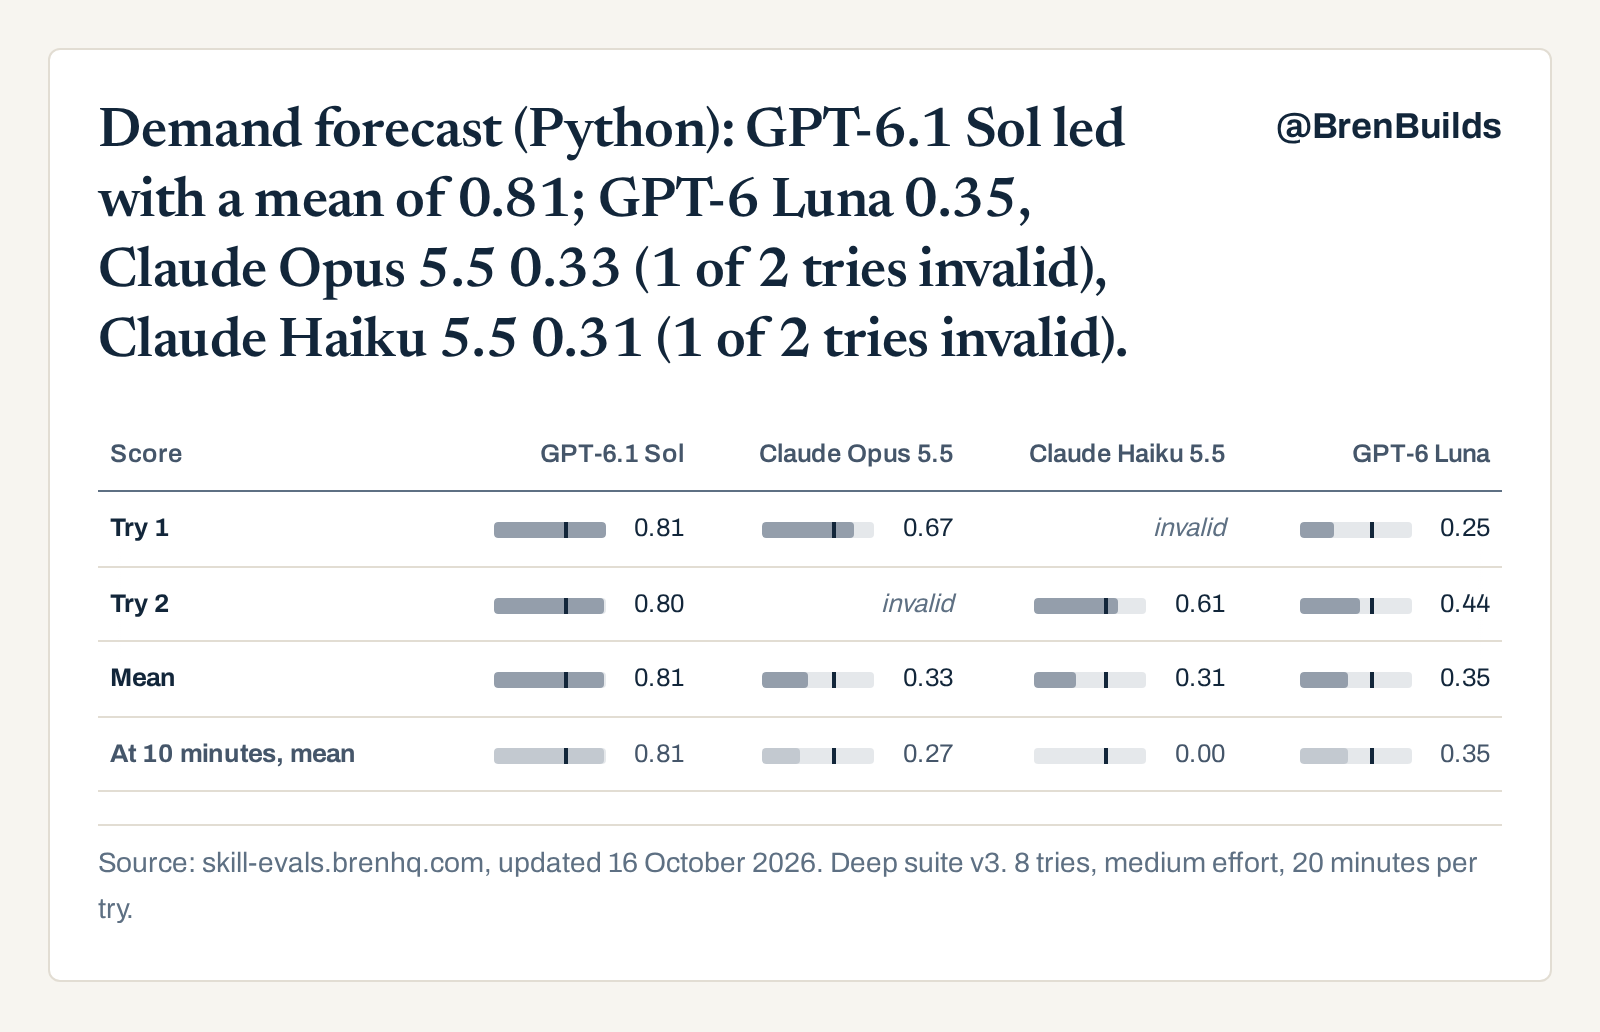
Demand forecast (Python): GPT-6.1 Sol led with a mean of 0.81; GPT-6 Luna 0.35, Claude Opus 5.5 0.33 (1 of 2 tries invalid), Claude Haiku 5.5 0.31 (1 of 2 tries invalid).
Forecast daily demand in our own app more accurately than its simple baseline. How much the forecast error shrank against the baseline, log2, averaged over hidden periods: 1 is about half the error. My own fix scored 0.52. An invalid try's code didn't build or broke the project's own tests; it counts as 0 in the mean. A try that finished before 10 minutes keeps its final score at 10 minutes.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Try 1 | 0.81 | 0.67 | invalid | 0.25 |
| Try 2 | 0.80 | invalid | 0.61 | 0.44 |
| Mean | 0.81 | 0.33 | 0.31 | 0.35 |
| At 10 minutes, mean | 0.81 | 0.27 | 0.00 | 0.35 |
Source: skill-evals.brenhq.com, updated 16 October 2026. Deep suite v3. 8 tries, medium effort, 20 minutes per try.
Correctness tasks#
These score the share of hidden checks, or hidden files, a try got right, from 0 to 1.
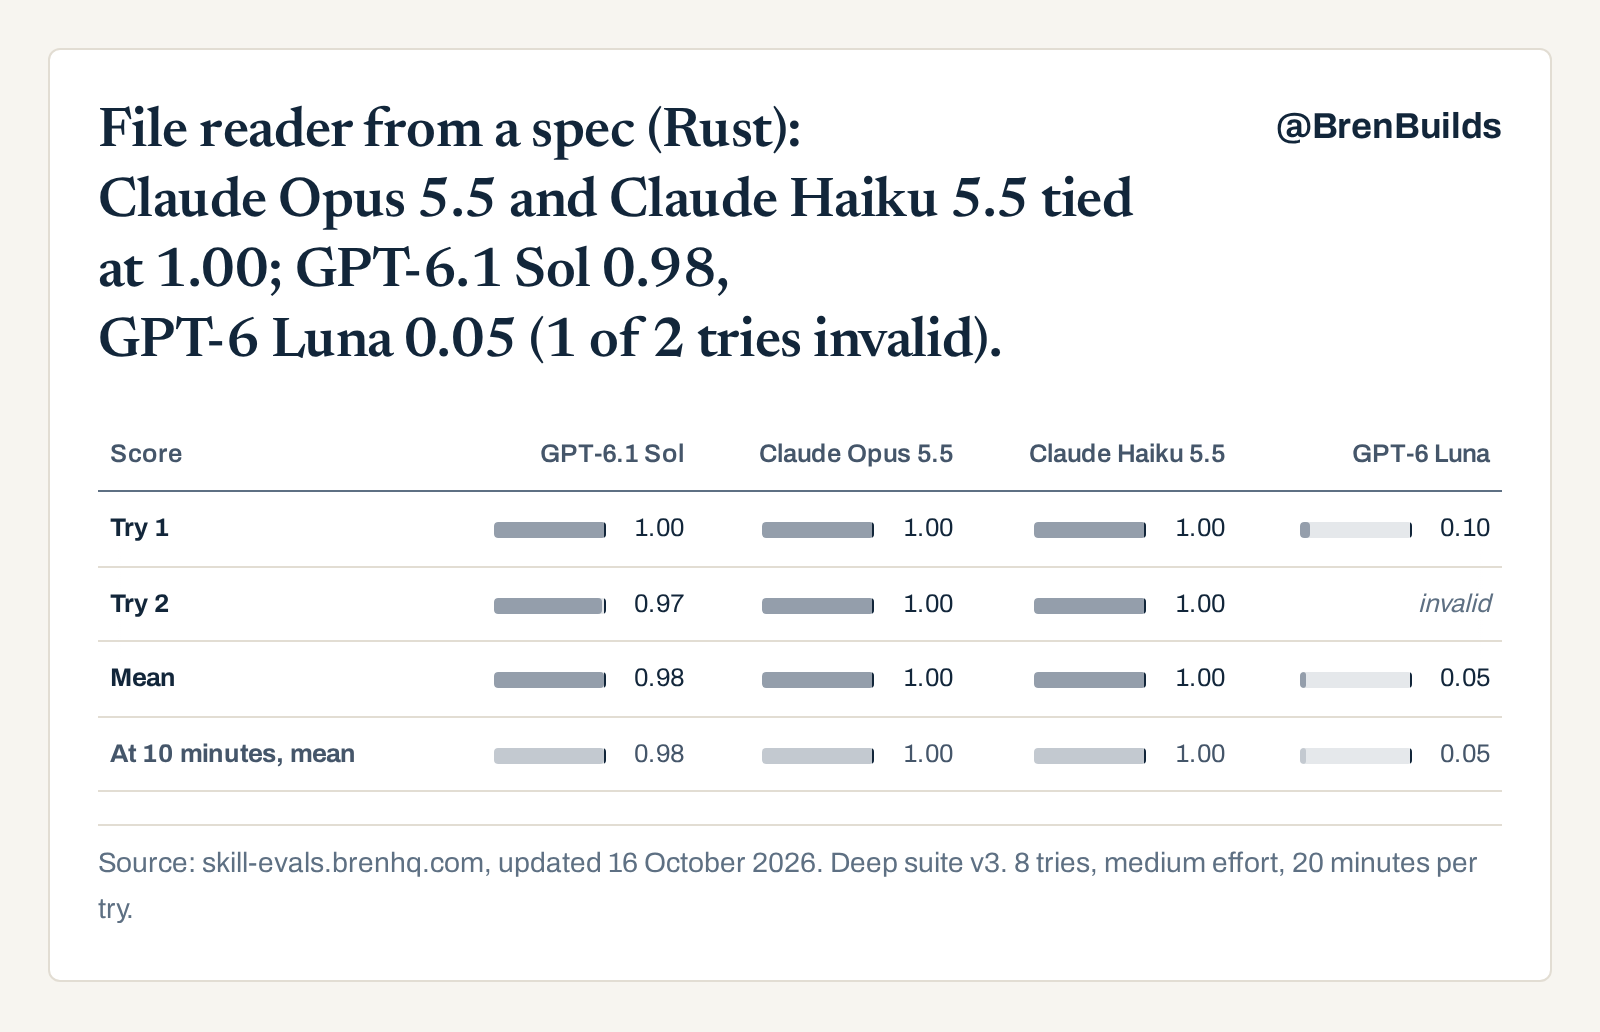
File reader from a spec (Rust): Claude Opus 5.5 and Claude Haiku 5.5 tied at 1.00; GPT-6.1 Sol 0.98, GPT-6 Luna 0.05 (1 of 2 tries invalid).
Write a reader for a data-file format from its public spec. The share of hidden files a try read exactly, 0 to 1. My own fix scored 1.00. An invalid try's code didn't build or broke the project's own tests; it counts as 0 in the mean. A try that finished before 10 minutes keeps its final score at 10 minutes.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Try 1 | 1.00 | 1.00 | 1.00 | 0.10 |
| Try 2 | 0.97 | 1.00 | 1.00 | invalid |
| Mean | 0.98 | 1.00 | 1.00 | 0.05 |
| At 10 minutes, mean | 0.98 | 1.00 | 1.00 | 0.05 |
Source: skill-evals.brenhq.com, updated 16 October 2026. Deep suite v3. 8 tries, medium effort, 20 minutes per try.
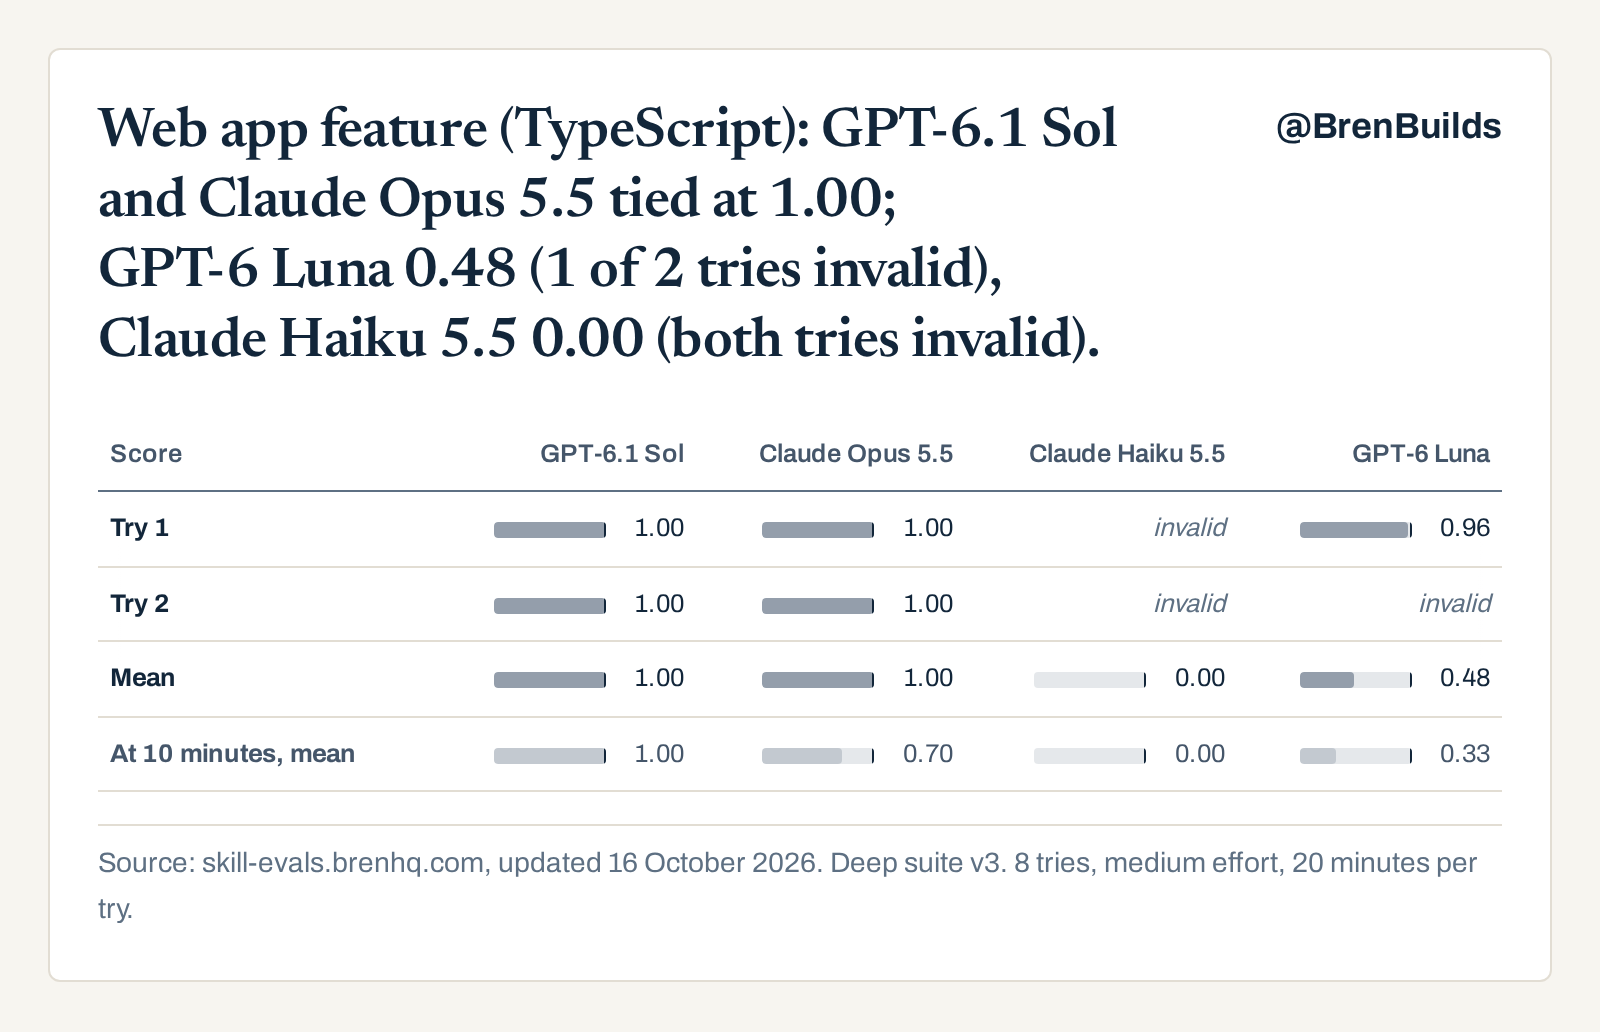
Web app feature (TypeScript): GPT-6.1 Sol and Claude Opus 5.5 tied at 1.00; GPT-6 Luna 0.48 (1 of 2 tries invalid), Claude Haiku 5.5 0.00 (both tries invalid).
Build a requested feature in a released open-source web app, end to end. The share of hidden checks a try passed, 0 to 1. My own fix scored 1.00. An invalid try's code didn't build or broke the project's own tests; it counts as 0 in the mean. A try that finished before 10 minutes keeps its final score at 10 minutes.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Try 1 | 1.00 | 1.00 | invalid | 0.96 |
| Try 2 | 1.00 | 1.00 | invalid | invalid |
| Mean | 1.00 | 1.00 | 0.00 | 0.48 |
| At 10 minutes, mean | 1.00 | 0.70 | 0.00 | 0.33 |
Source: skill-evals.brenhq.com, updated 16 October 2026. Deep suite v3. 8 tries, medium effort, 20 minutes per try.
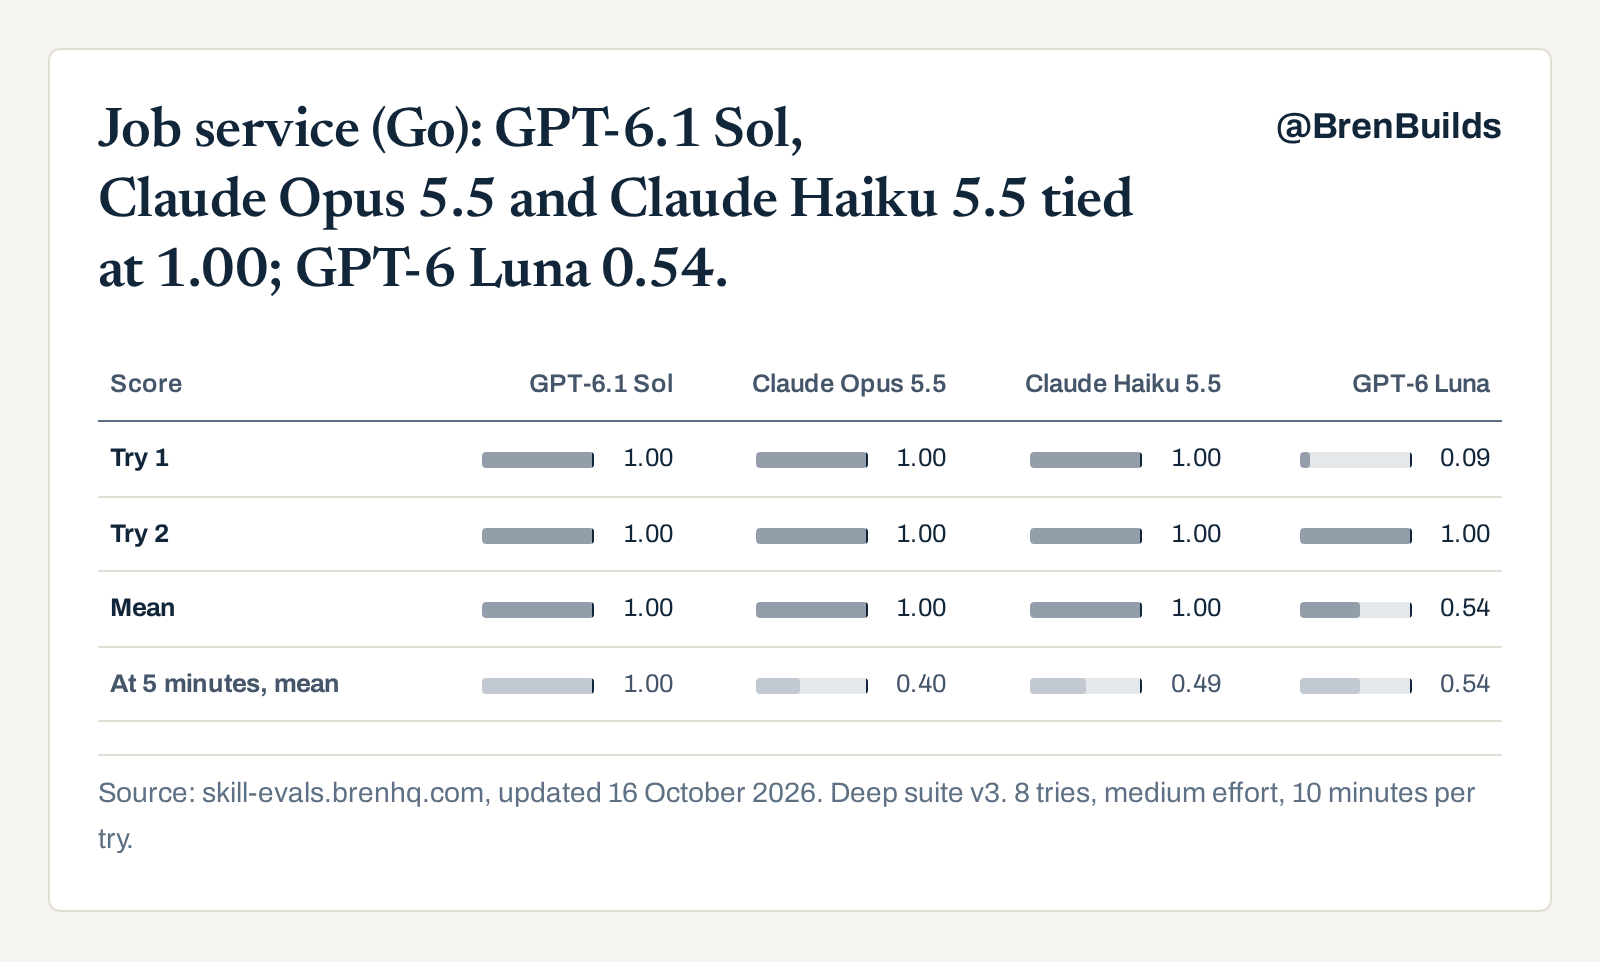
Job service (Go): GPT-6.1 Sol, Claude Opus 5.5 and Claude Haiku 5.5 tied at 1.00; GPT-6 Luna 0.54.
Ship two planned releases of our own job service, the second built on the first. The share of hidden checks a try passed, 0 to 1. My own fix scored 1.00. A try that finished before 5 minutes keeps its final score at 5 minutes.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Try 1 | 1.00 | 1.00 | 1.00 | 0.09 |
| Try 2 | 1.00 | 1.00 | 1.00 | 1.00 |
| Mean | 1.00 | 1.00 | 1.00 | 0.54 |
| At 5 minutes, mean | 1.00 | 0.40 | 0.49 | 0.54 |
Source: skill-evals.brenhq.com, updated 16 October 2026. Deep suite v3. 8 tries, medium effort, 10 minutes per try.
Time#
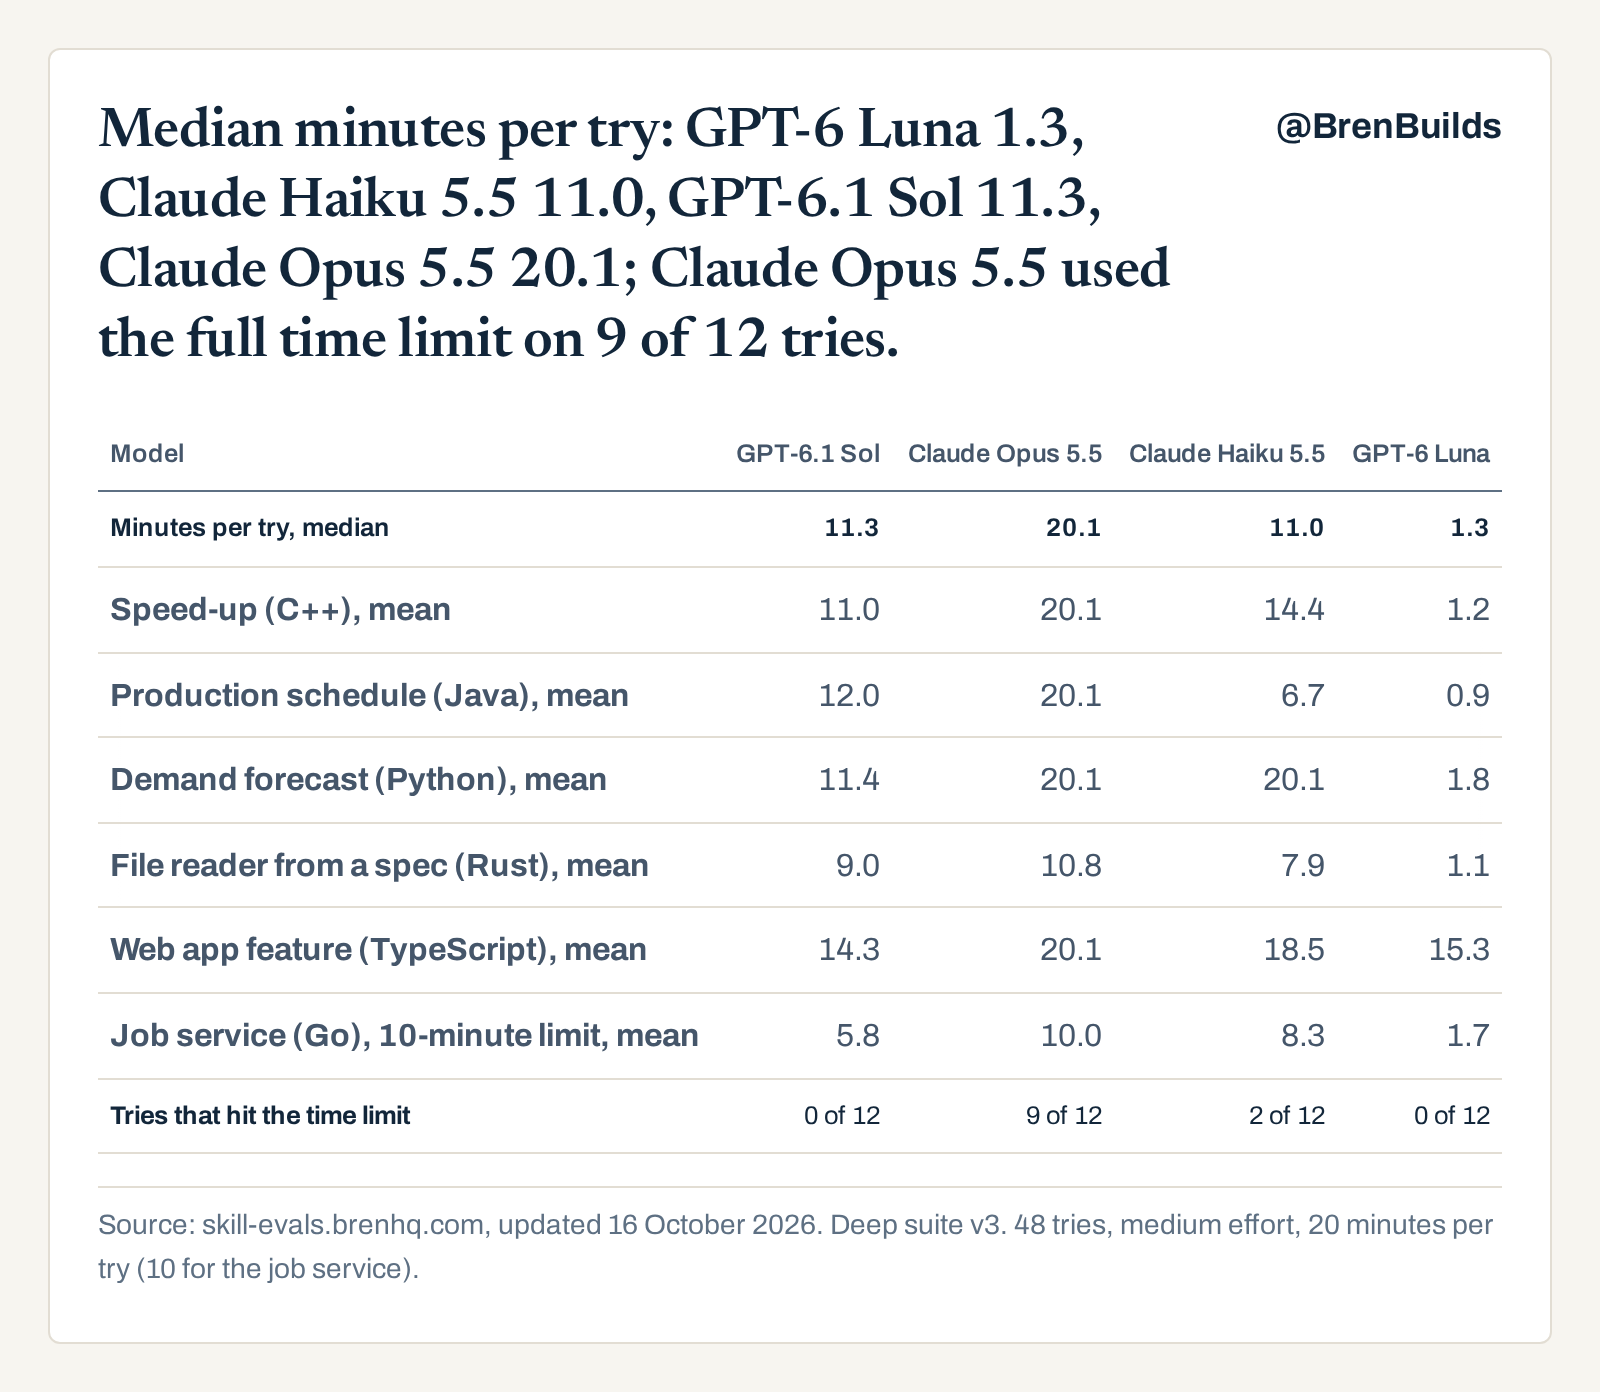
Median minutes per try: GPT-6 Luna 1.3, Claude Haiku 5.5 11.0, GPT-6.1 Sol 11.3, Claude Opus 5.5 20.1; Claude Opus 5.5 used the full time limit on 9 of 12 tries.
Minutes from start to finish, including stopping the tools, so a try stopped at the limit can read a little over it. A short try can mean a model stopped early, so read time beside the scores.
| Model | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Minutes per try, median | 11.3 | 20.1 | 11.0 | 1.3 |
| Speed-up (C++), mean | 11.0 | 20.1 | 14.4 | 1.2 |
| Production schedule (Java), mean | 12.0 | 20.1 | 6.7 | 0.9 |
| Demand forecast (Python), mean | 11.4 | 20.1 | 20.1 | 1.8 |
| File reader from a spec (Rust), mean | 9.0 | 10.8 | 7.9 | 1.1 |
| Web app feature (TypeScript), mean | 14.3 | 20.1 | 18.5 | 15.3 |
| Job service (Go), 10-minute limit, mean | 5.8 | 10.0 | 8.3 | 1.7 |
| Tries that hit the time limit | 0 of 12 | 9 of 12 | 2 of 12 | 0 of 12 |
Source: skill-evals.brenhq.com, updated 16 October 2026. Deep suite v3. 48 tries, medium effort, 20 minutes per try (10 for the job service).
Cost#
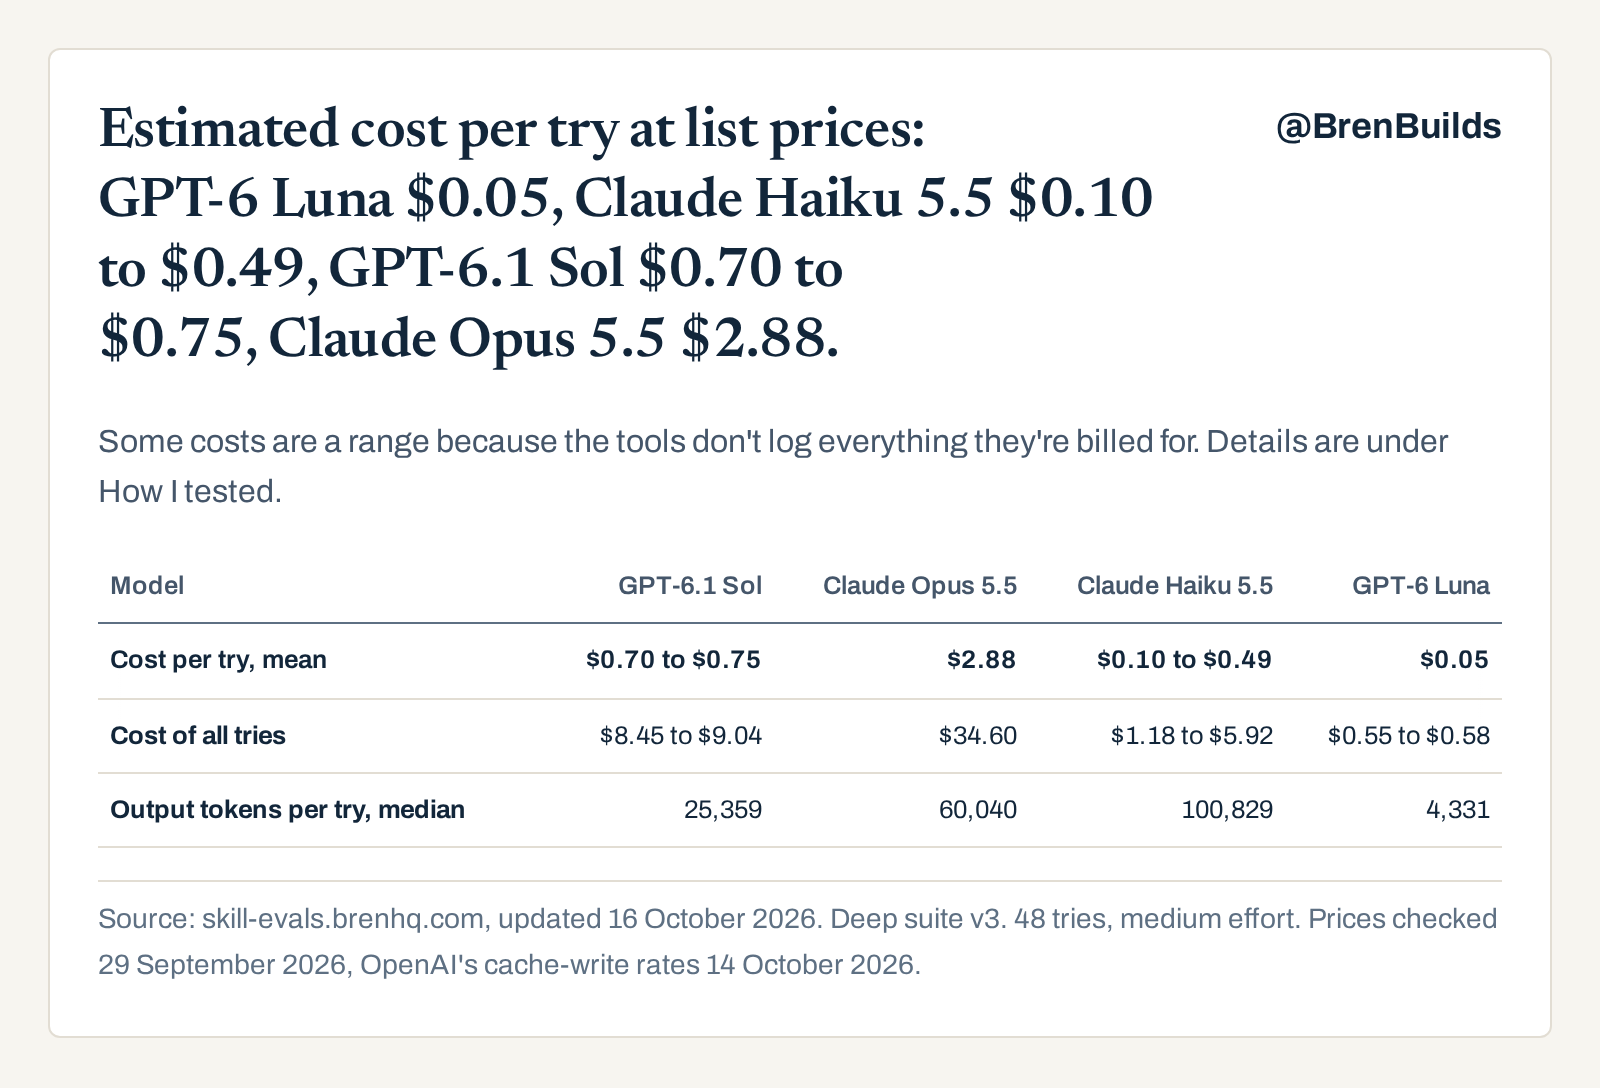
Estimated cost per try at list prices: GPT-6 Luna $0.05, Claude Haiku 5.5 $0.10 to $0.49, GPT-6.1 Sol $0.70 to $0.75, Claude Opus 5.5 $2.88.
An estimate at each vendor's list prices from the tokens each try used, invalid tries included. 11 Claude tries hit the time limit before Claude Code logged usage, so their tokens were counted from each try's own requests. The tries ran on subscriptions, so this is not what was spent.
Some costs are a range because the tools don't log everything they're billed for. Details are under How I tested.
| Model | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Cost per try, mean | $0.70 to $0.75 | $2.88 | $0.10 to $0.49 | $0.05 |
| Cost of all tries | $8.45 to $9.04 | $34.60 | $1.18 to $5.92 | $0.55 to $0.58 |
| Output tokens per try, median | 25,359 | 60,040 | 100,829 | 4,331 |
Source: skill-evals.brenhq.com, updated 16 October 2026. Deep suite v3. 48 tries, medium effort. Prices checked 29 September 2026, OpenAI's cache-write rates 14 October 2026.
How I tested#
How the tasks were made, run and graded
In version 2 the two strongest models passed every try, so its scores couldn't tell them apart. For version 3 I wrote six tasks in six languages: two in real open-source code as released, four in applications I wrote for the suite. Three are open-ended: they measure how much a try improved the code, on a log2 scale, and aren't capped at my own fix's score; the other three score the share of hidden checks a try gets right. Each task keeps its own score, so there is no overall number or rank. Tasks, prompts and graders are private so later runs stay fair.
The hidden checks and hidden data never enter the model's container, and every model got the same seeds. A try whose code doesn't build or breaks the project's own tests is invalid and scores 0. Fable 5.1 and GPT-6 Astra reviewed the plan before the counted runs began; trial runs aren't counted.
This is version 3, frozen 15 October 2026: 6 tasks, 2 tries each, the same settings and the same containers for every model. Each version tests something different, so scores don't carry over from earlier versions.
Claude Opus 5.5 and Claude Haiku 5.5 ran in Claude Code 2.1.284, and GPT-6.1 Sol and GPT-6 Luna in Codex CLI 0.159.0, all at medium effort, 20 minutes per try (10 for the job service). The code was saved at the halfway point without stopping the model, and that copy was graded too. 11 tries hit the limit and were graded on the code at that point. Each try ran in its own container with no internet except the model's API, and was graded in a fresh container. Tasks that measure time were graded one try at a time with nothing else running. Runs were paced to stay under a fixed share of each subscription's usage.
Costs are estimates at each vendor's standard API prices, from the tokens each try used. Claude Code logs no usage for a try stopped at the time limit, so for those 11 Claude tries I counted the tokens from the try's own requests, the same way Claude Code counts them on tries that finished. Claude Haiku 5.5 is a range because Anthropic charges more for prompts over 100k tokens and prompt sizes weren't logged; GPT costs are a range because Codex doesn't log cache writes, which OpenAI bills at 1.25 times the input price. The tries ran on subscriptions, so these are not what was spent.
Limits: 6 tasks and 2 tries each, one tool and one effort setting per model. Two tries can't show which gaps would hold up over more runs, so none is called significant here.
Every try's task, score, time and cost is in results.json, under deep_v3_runs and deep_v3_suite.